Lecture: Principal Component Analysis
Ordination by eigen-decomposition
Last Week: The Multivariate Toolkit
Three steps, in order
- Standardize — because units are not biology.
- Choose a distance — Euclidean for continuous traits, Bray–Curtis for species counts, Jaccard for presence–absence. This is the modelling decision.
- Ordinate — draw the resemblances on a readable 2-D map.
Where PCA sits
- PCA is the eigen-decomposition branch of that map: it works on a correlation or covariance matrix, implies Euclidean distance, and assumes linear relationships.
- In exchange it gives you ordered axes, % variance explained, and loadings — which NMDS cannot.
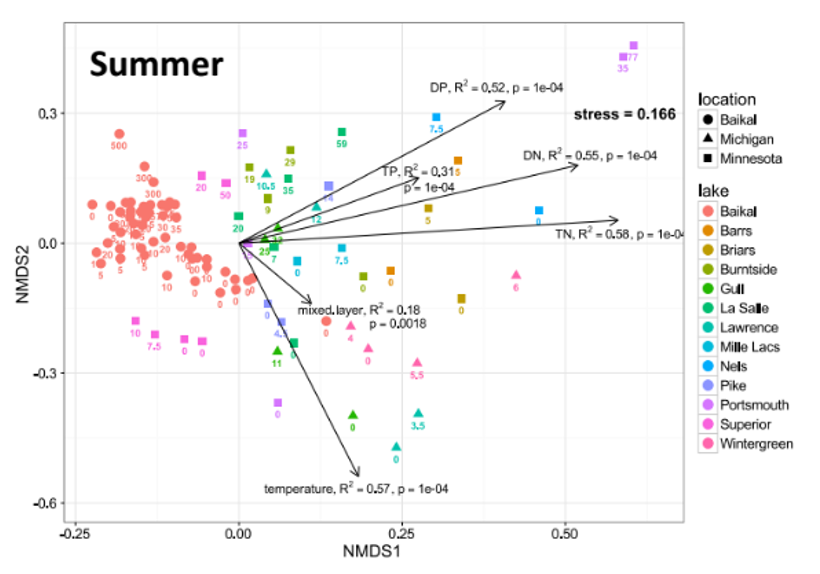
An ordination of the kind we are building toward.
Today’s Data: Iris
Four measurements, three species
- 150 flowers, 4 measurements (cm), 50 from each of three species.
- Small enough to follow every number by hand, correlated enough for PCA to have something to do.
- The test we will apply: PCA is never told which species a flower belongs to. Does it recover them anyway?
The Problem PCA Solves
Four dimensions is already too many
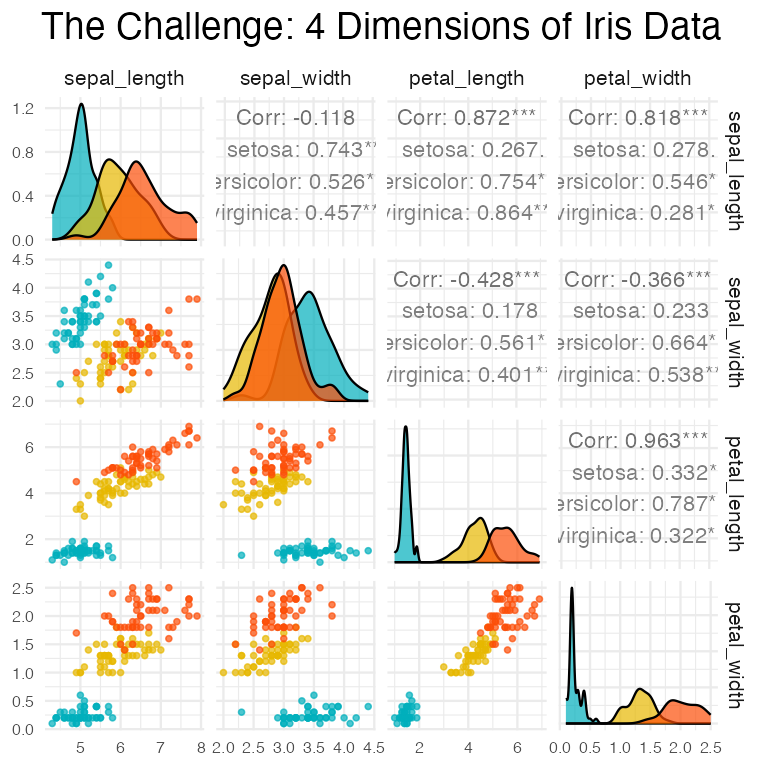
- With 4 variables there are 6 pairwise scatterplots. With 10 there are 45. With 27 there are 351.
- No set of 2-D plots shows you how all the variables move together.
- PCA’s offer: a small number of new axes, built from the old ones, that carry most of the information.
- And it will do it without being told about species.
PCA Is a Rotation
The 2-variable picture
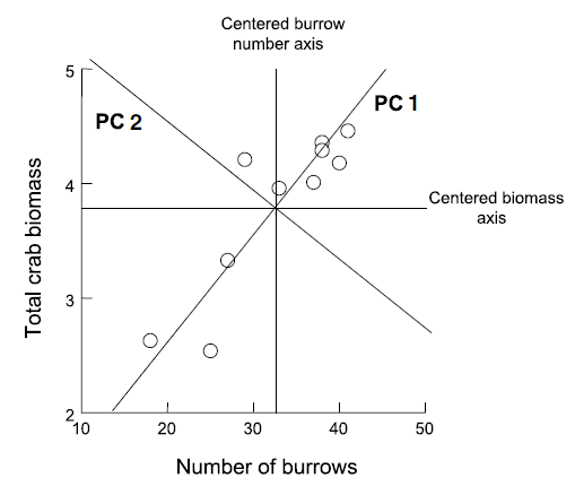
- Start with two correlated variables — crab burrows and crab biomass. The cloud of points runs diagonally.
- The original axes are a bad description: both of them carry some of the same information.
- PCA keeps the points exactly where they are and turns the axes until the first one lies along the direction of greatest spread.
- Nothing is lost in a rotation. The distances between points are identical before and after.
The Same Data, New Axes
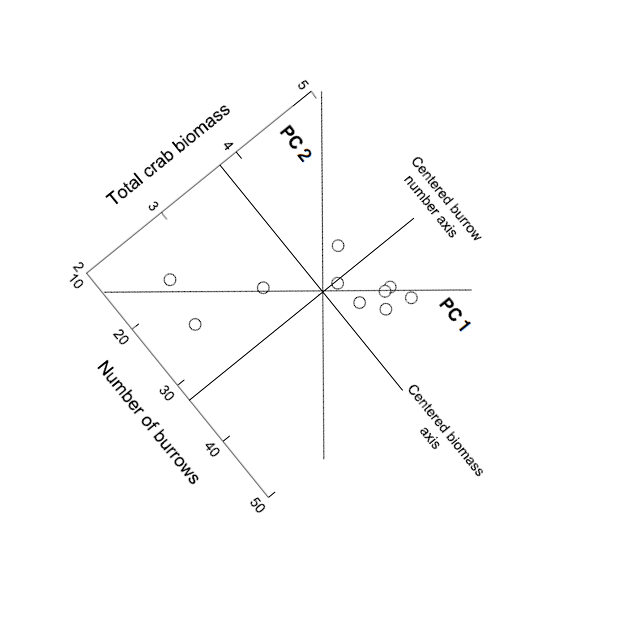
After the rotation
- PC1 is now horizontal and carries most of the spread; PC2 is vertical and carries what is left.
- The two new axes are orthogonal, which is the geometric way of saying the two components are uncorrelated.
- The old variables are still in there — they are now the diagonal reference lines, and the angle each one makes with PC1 is exactly what its loading records.
- The rotation is chosen to maximize the variance on PC1. That one sentence is the whole of PCA.
Beyond Two Dimensions
Same idea, more axes
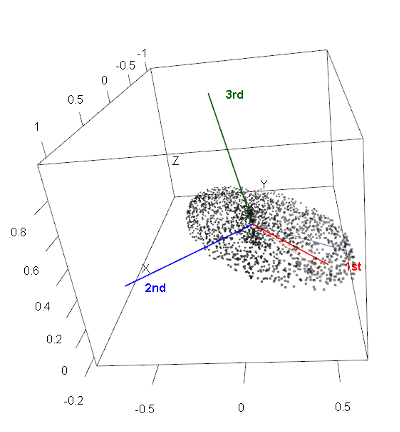
- In 3-D the rotation finds a first axis through the long direction of the cloud, a second at right angles to it through the longest remaining direction, and a third fixed by the first two.
- With p variables you get exactly p components — the rotation uses up every dimension.
- You do not do this by eye. The components are extracted from the p × p covariance or correlation matrix of the original variables, and the extraction is an eigen-decomposition.
What PCA Assumes
Check these first
- Linear relationships between variables — PCA sees only straight lines.
- No extreme outliers — one wild object can define a whole component.
- Variables are correlated — otherwise there is nothing to collapse.
- Adequate sample size — at least 3× as many objects as variables; n > 50 is comfortable. We have 150 flowers and 4 variables.
- Complete cases —
prcomp()will not handle missing values for you.
Are the iris variables correlated?
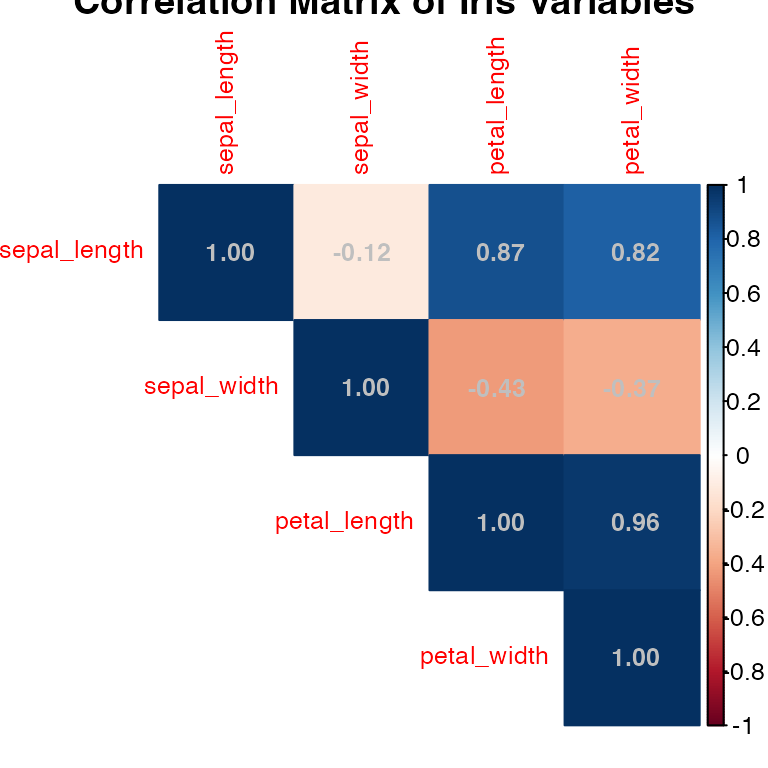
- Petal length and petal width correlate at 0.96. Plenty of redundancy to collapse.
Checking Linearity and Outliers
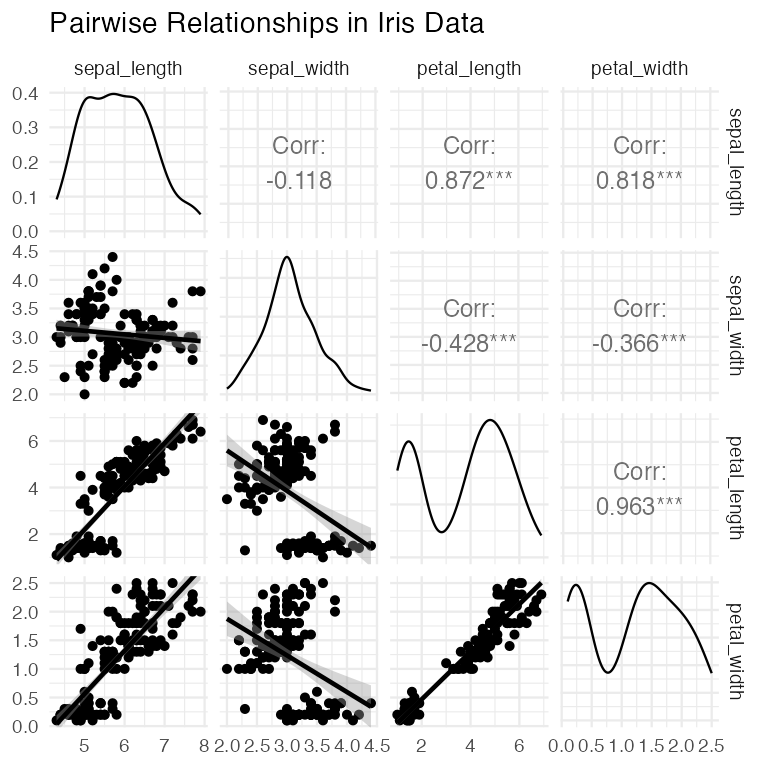
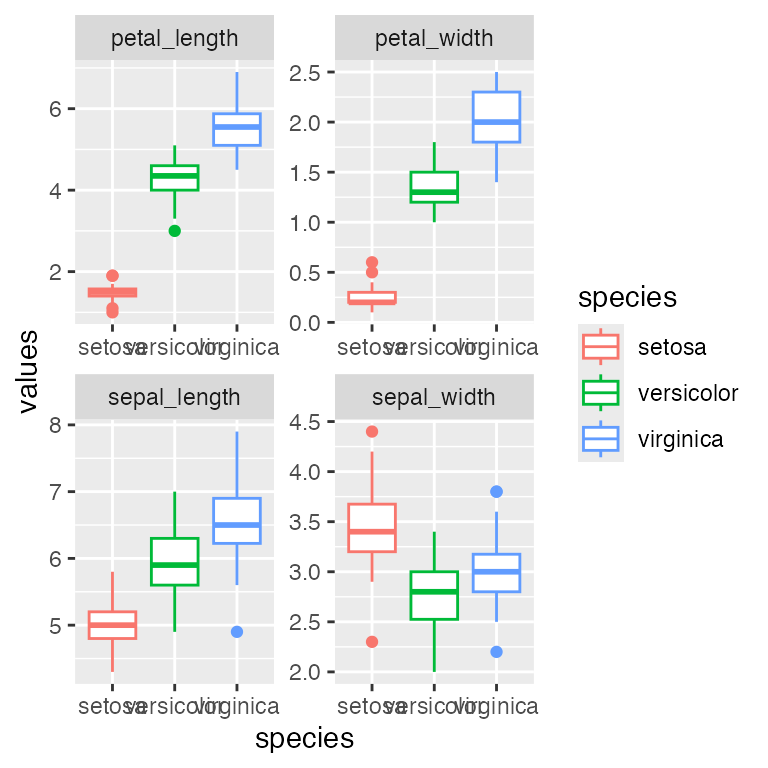
Relationships are close to straight lines — the setosa cluster makes some panels look bent, but within species they are linear.
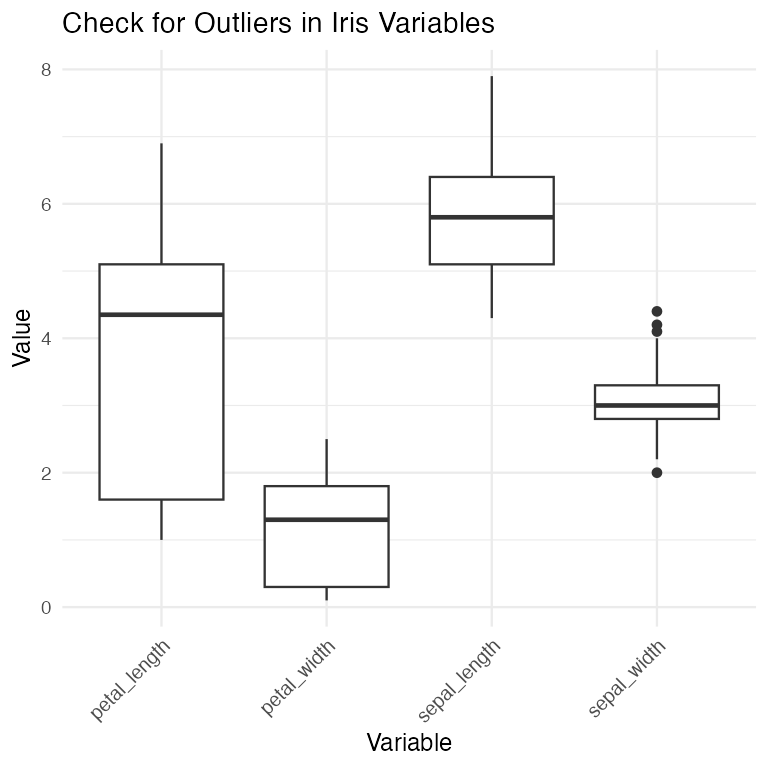
A handful of mild sepal-width outliers, nothing extreme. Note how much wider petal length spreads than sepal width — that is the standardization problem in one picture.
The Scree Plot
What it is
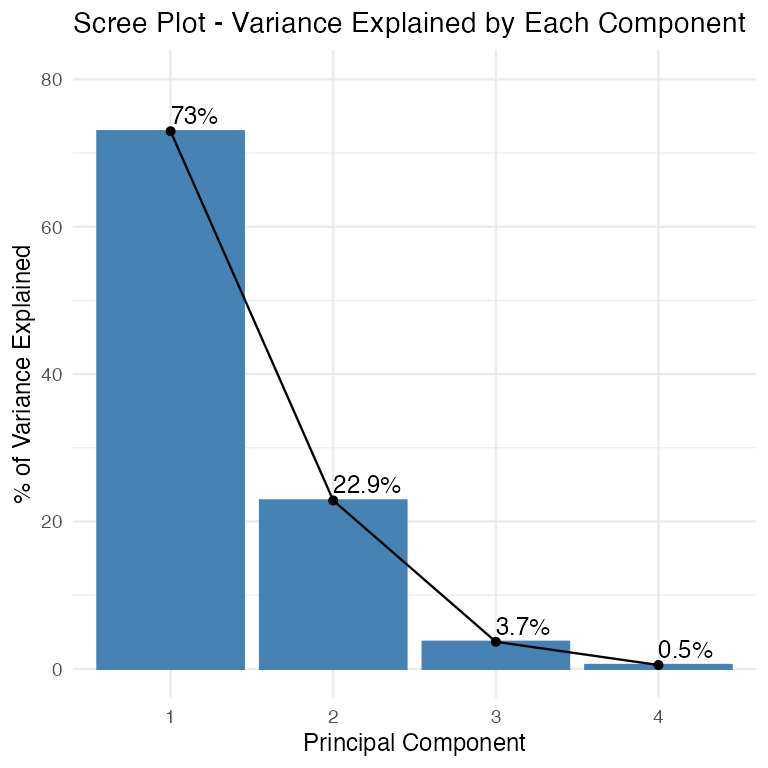
- “Scree” is the geological term for the loose rubble at the base of a cliff. The plot usually shows a cliff then rubble.
- Y-axis: % variance explained. X-axis: component number.
- The elbow method: find where the line stops dropping steeply and flattens out. Keep the components before the flattening.
- Here the cliff runs PC1 → PC2 and the rubble starts at PC3. The elbow says keep two.
The Loading Plot
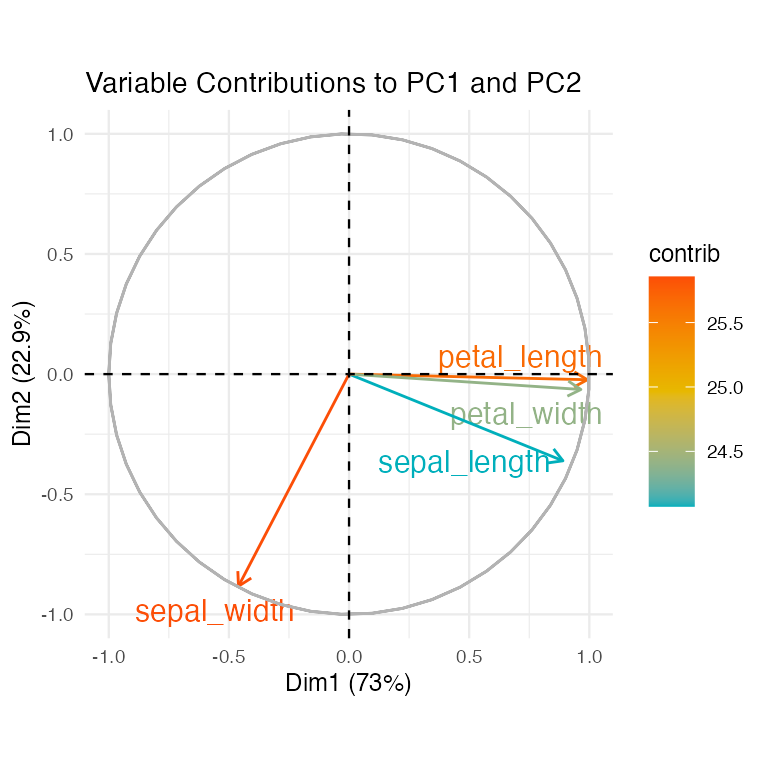
Reading the arrows
- Direction = which components the variable builds. Length = how well this plane represents it. The circle is the maximum possible.
- Petal length, petal width and sepal length point right — they build positive PC1 together, and their small mutual angles say they are strongly correlated.
- Sepal width points down and slightly left — nearly at right angles to the petals, which is the plot’s way of saying it carries almost independent information.
- That near-90° angle is why sepal width got its own component.
Scores: Where Each Flower Lands
From loadings to positions
- A score is an object’s coordinate on a component — the result of the recipe, applied to that object’s standardized values.
iris_pca$xholds them, 150 rows × 4 components.
## # A tibble: 9 × 5
##   species      PC1   PC2   PC3   PC4
##   <fct>      <dbl> <dbl> <dbl> <dbl>
## 1 setosa     -2.26 -0.48  0.13  0.02
## 2 setosa     -2.07  0.67  0.23  0.1
## 3 setosa     -2.36  0.34 -0.04  0.03
## 4 versicolor  1.1  -0.86  0.68  0.03
## 5 versicolor  0.73 -0.59  0.09  0
## 6 versicolor  1.24 -0.61  0.55  0.01
## 7 virginica   1.84 -0.87 -1    -0.05
## 8 virginica   1.15  0.7  -0.53 -0.04
## 9 virginica   2.2  -0.56  0.2   0.06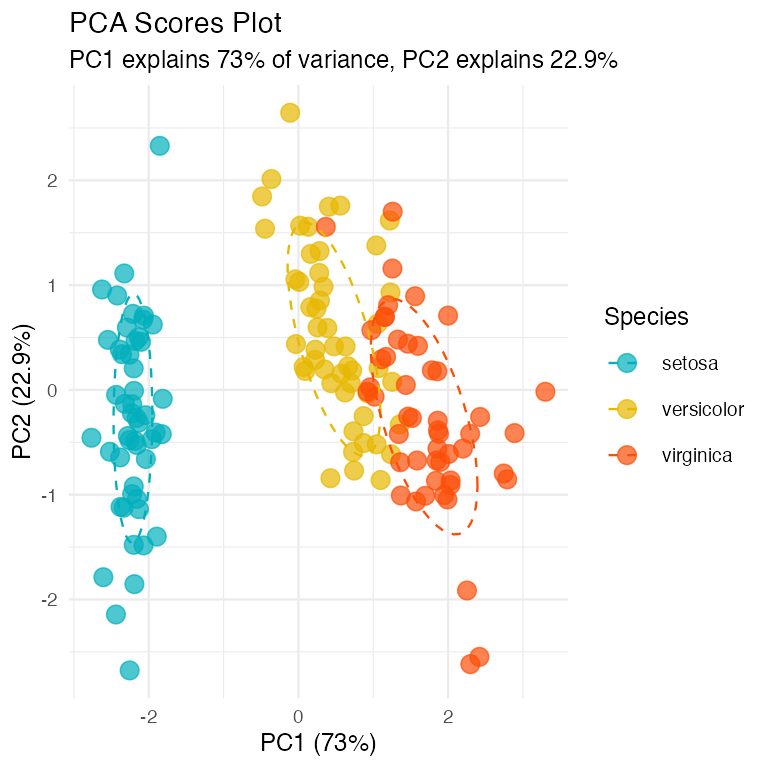
The Biplot
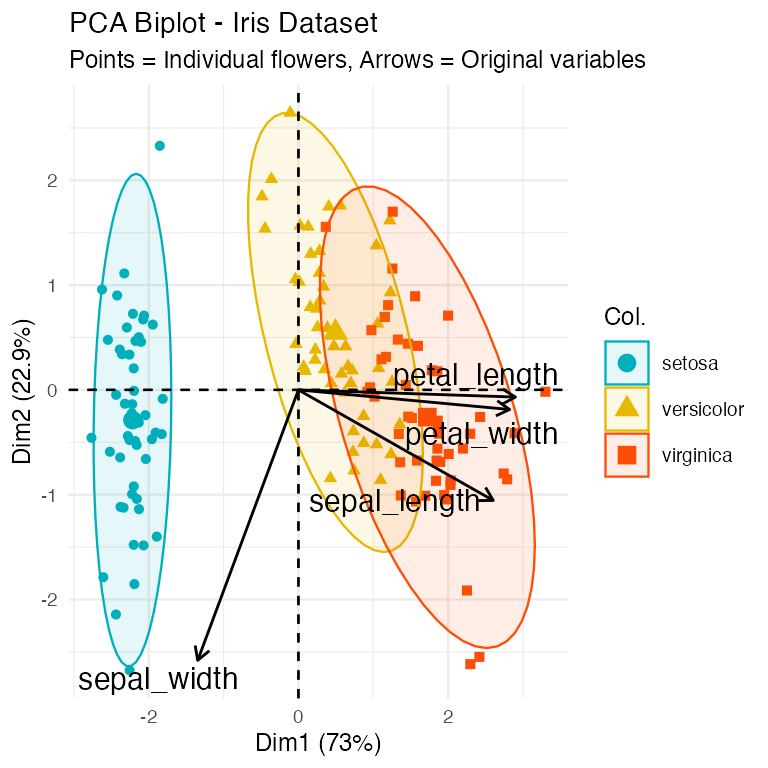
Points and arrows together
- Points = flowers (scores). Arrows = variables (loadings), on the same plane.
- A flower lying out along an arrow is high in that variable.
- Setosa sits far left — low PC1, so short petals and sepals, but (per PC1’s negative sepal-width loading) broad sepals.
- Virginica sits right — long petals and sepals, narrower sepals.
- Versicolor sits between, overlapping virginica slightly.
- PCA was never told about species. It recovered them from morphology alone.
The Same PCA, Three Other Packages
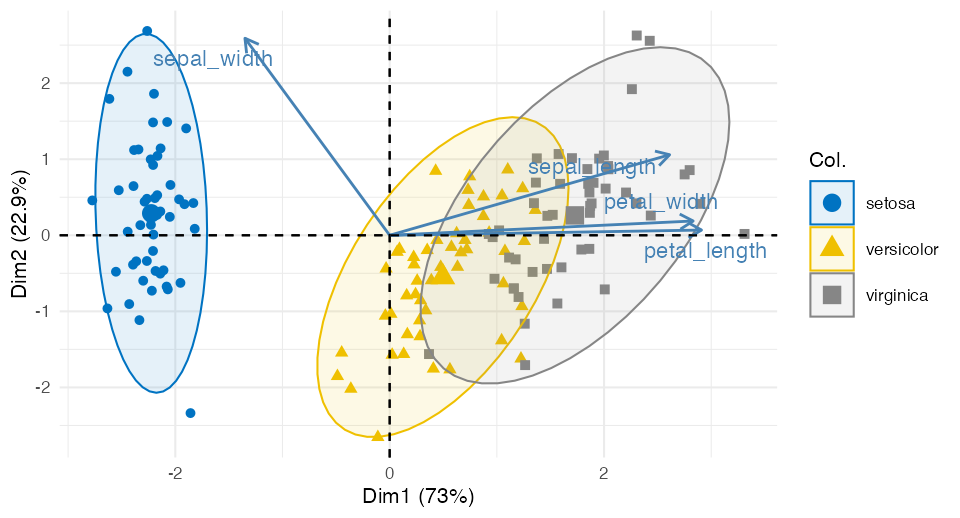
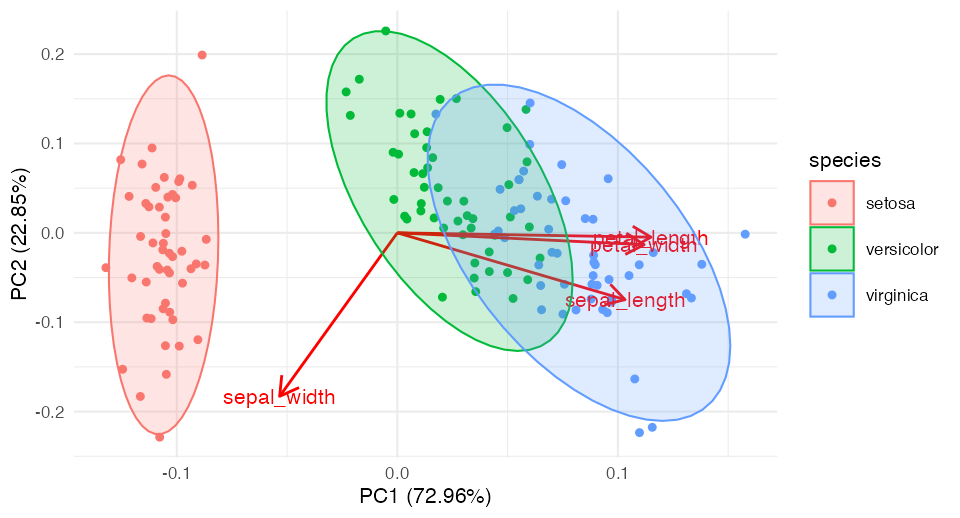
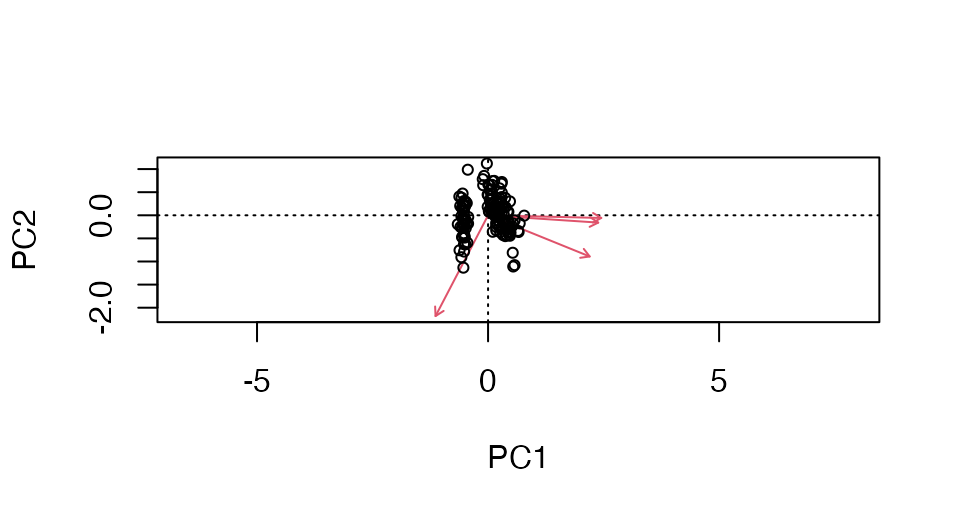
- All four routes decompose the same matrix. The numbers are identical; only the plotting defaults and the sign conventions differ.