Lecture: Probability & Inference
From the normal curve to the confidence interval
The normal distribution
A probability distribution spreads probability across the possible outcomes — but how depends on the data:
- Discrete (a die): each outcome has its own probability, P(4) = 1/6
- Continuous (fish length): any exact value has probability zero. Probability lives in ranges, as area under the curve
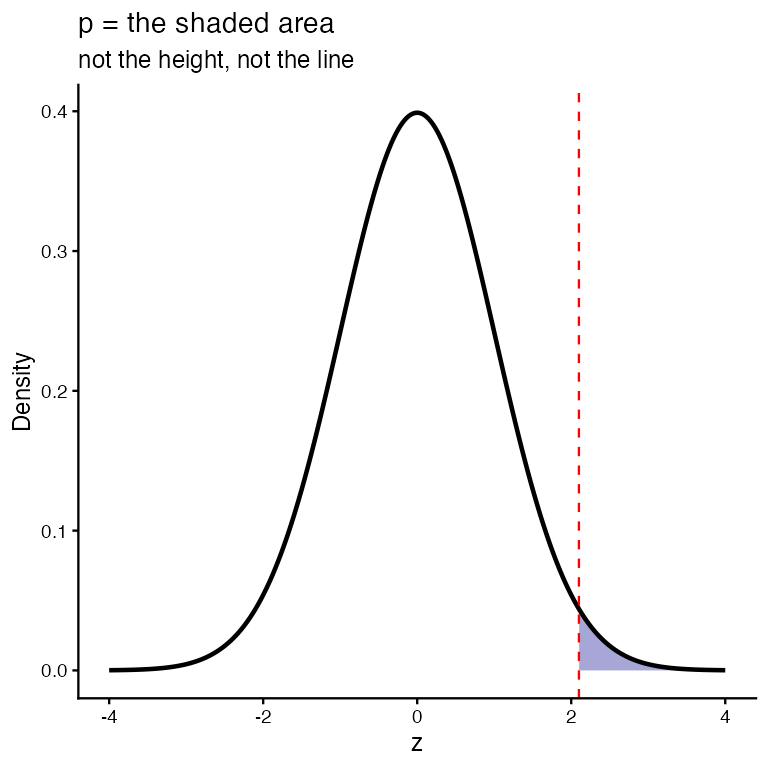
The curve’s height is a density — probability per mm, not a probability. Density × width ≈ probability.
Density is a rate, so it is not capped at 1:
dnorm(0, sd = 0.1)= 3.989. Nothing is 399% likely — proof that height ≠ probability.
The normal is the density we lean on: symmetric, fixed by μ (where it sits) and σ (how wide), total area 1.
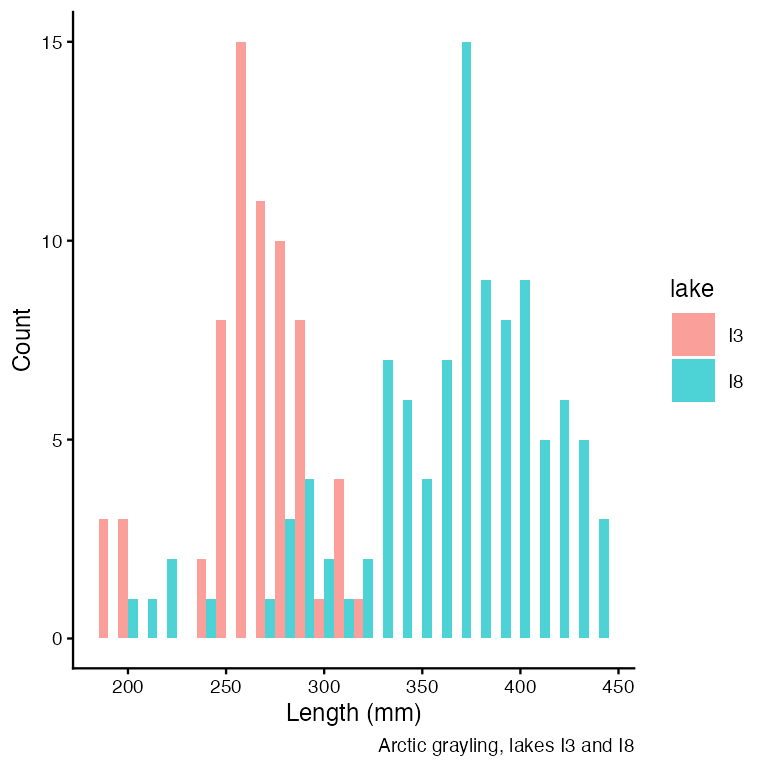
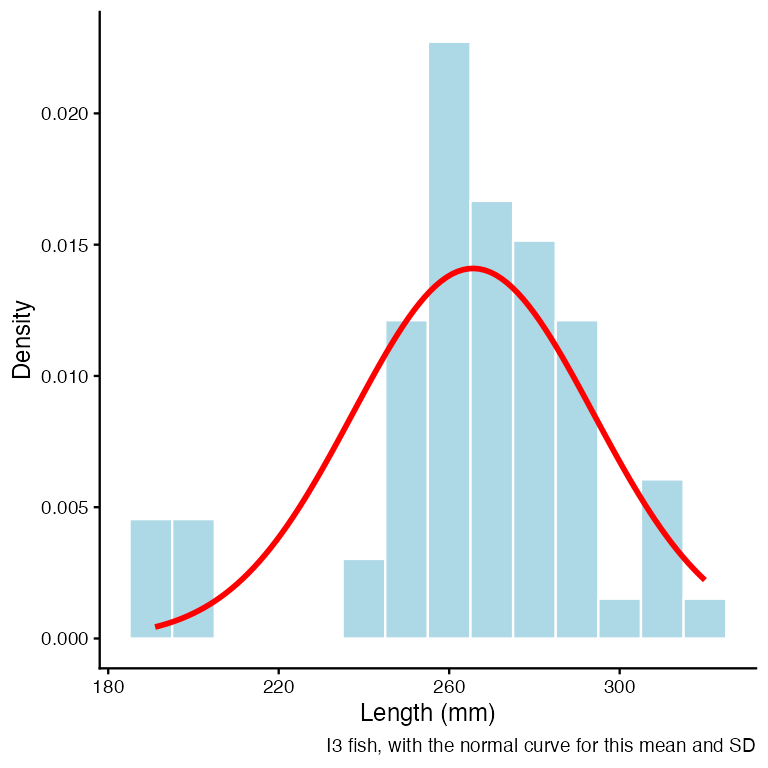
Lake I3: μ ≈ 265.6 mm, σ ≈ 28.3 mm — our curve. Every dataset has its own.
Why we standardize
There is a different normal curve for every μ and σ. Nobody can tabulate infinitely many curves.
So we rescale every value into the same units — standard deviations from the mean:
\(z = \frac{x_i - \mu}{\sigma}\)
- \(x_i\) = the observation
- \(μ\) = mean of the distribution
- \(σ\) = standard deviation of the distribution
Subtracting μ slides the curve to centre 0. Dividing by σ squeezes it to width 1.
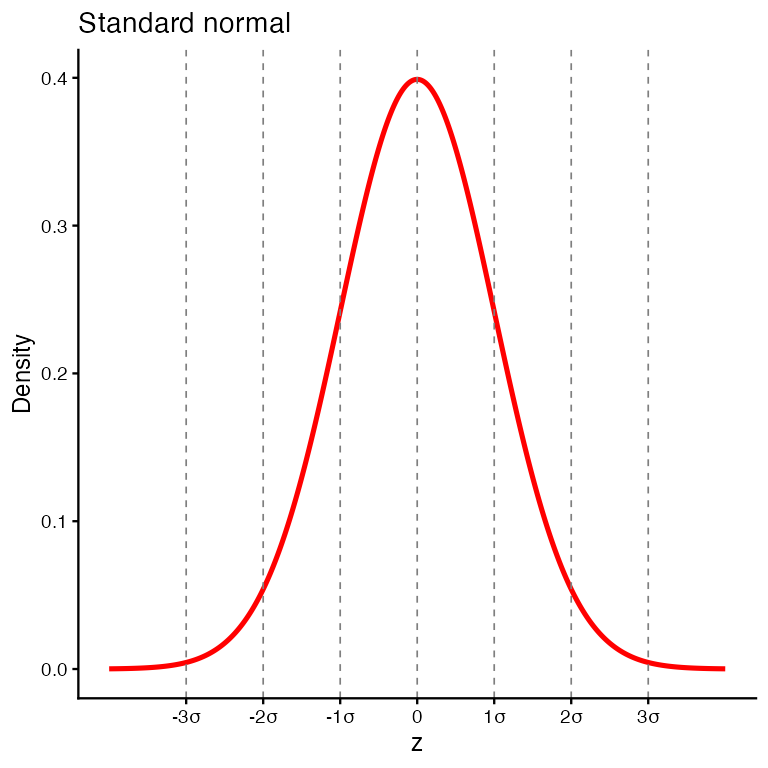
The result is the standard normal distribution: μ = 0, σ = 1. One curve. One table.
A z-score is not a new measurement. It is the same fish, expressed as “how many SDs from average.”
The same fish, two sets of units
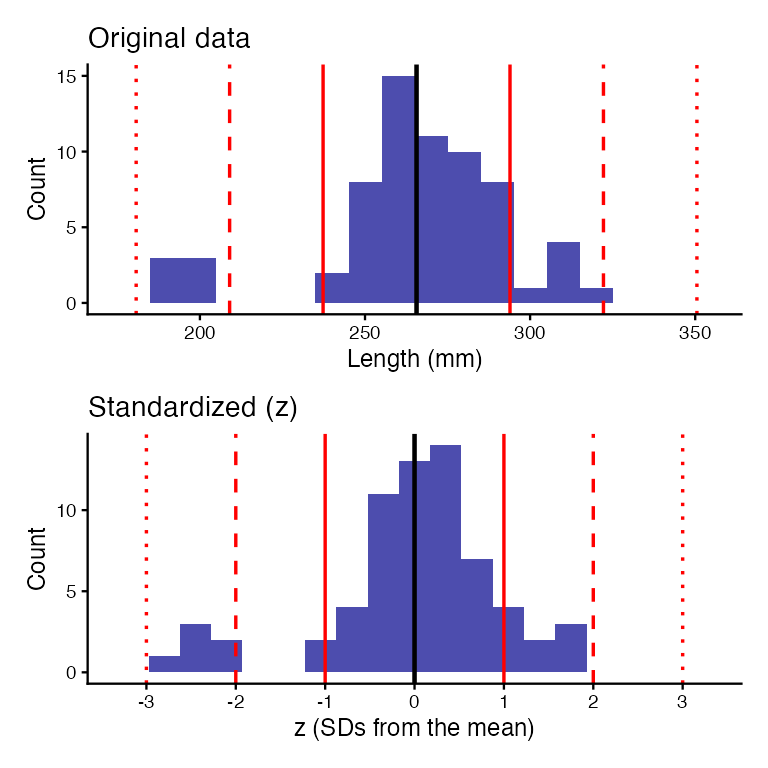
Standardizing changes the axis labels, not the shape.
- Top: millimetres, centred near 266
- Bottom: z, centred at 0
- Same fish, same bars, same skew — only the ruler changed
That matters: standardizing does not make non-normal data normal. It only puts it on a common ruler. We come back to this in Part 3.
The 68–95–99.7 rule
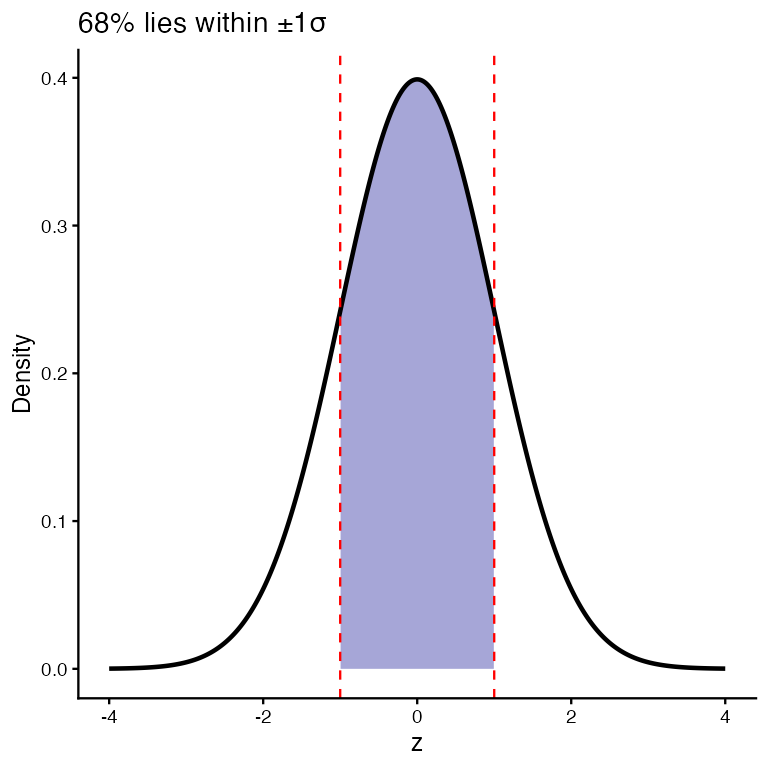
Because the standard normal is one fixed curve, its areas are fixed too:
- 68% of the curve within ±1σ
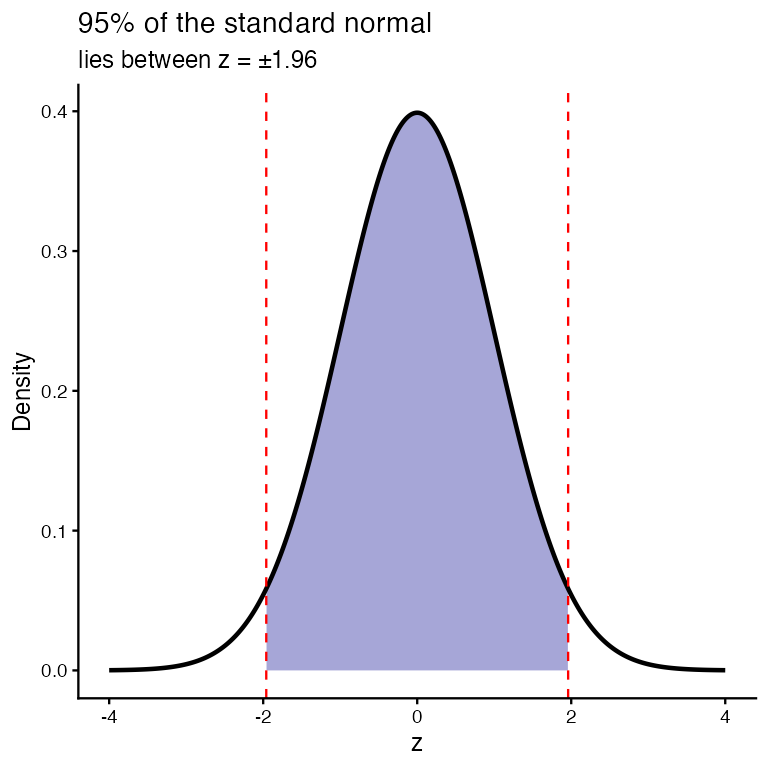
- 95% within ±1.96σ — “±2” is the rule of thumb, 1.96 is the number
- 99.7% within ±3σ
Our I3 fish, counted directly:
[1] 81.8Theory says 68%. We get 81.8%.
Hold that gap. It is the whole point of Part 3.
pnorm, qnorm, dnorm — which is which
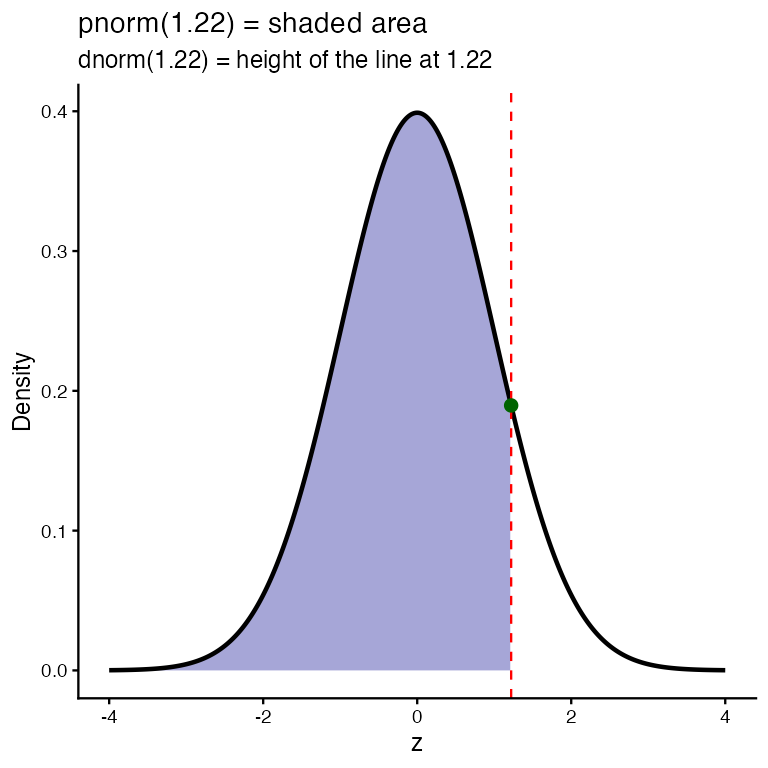
All three describe the same standard normal curve. They differ in what you hand them and what you get back.
| Function | You give it | You get back |
|---|---|---|
pnorm(z) |
a z | the area to the left of it |
qnorm(p) |
an area | the z that cuts it off |
dnorm(z) |
a z | the height of the curve |
p= probability,q= quantile — and they are inversesdnormis the curve’s height, used to draw it. A height is not a probability — only area is
Reading the z-table
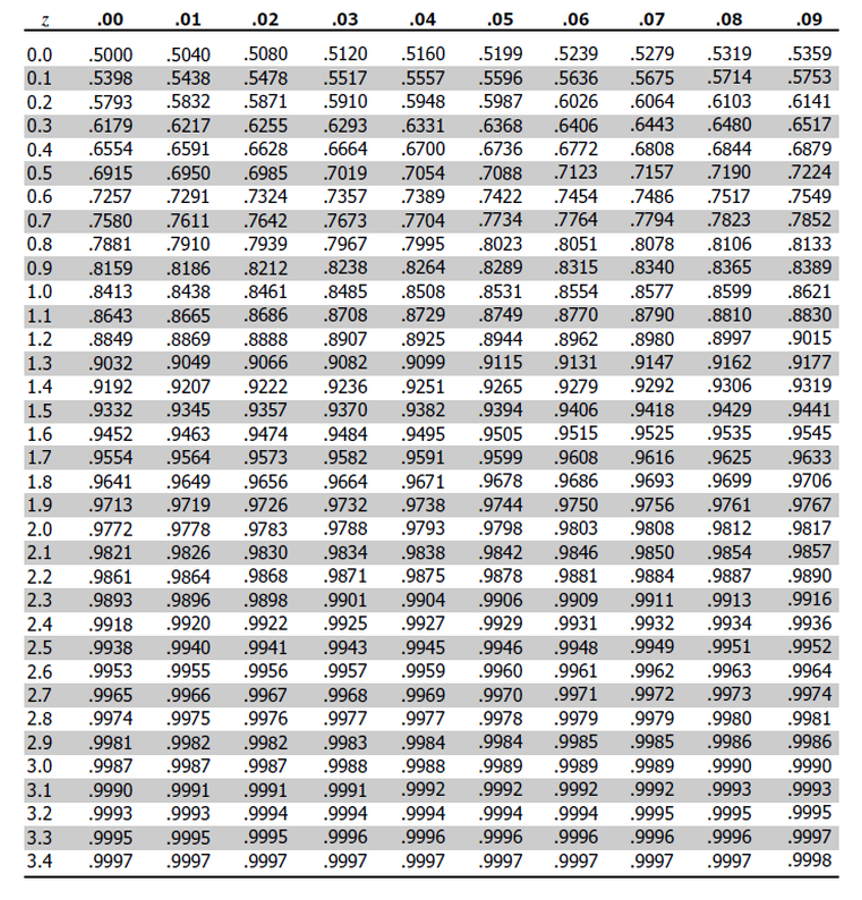
The z-table is pnorm() printed on paper: cumulative area to the LEFT of z.
- Find the ones and tenths of z down the left column
- Find the hundredths across the top
- Read the area where they meet
One table works for every dataset — because every dataset gets standardized first. (Contrast the t-table later, which needs a row for each sample size.)
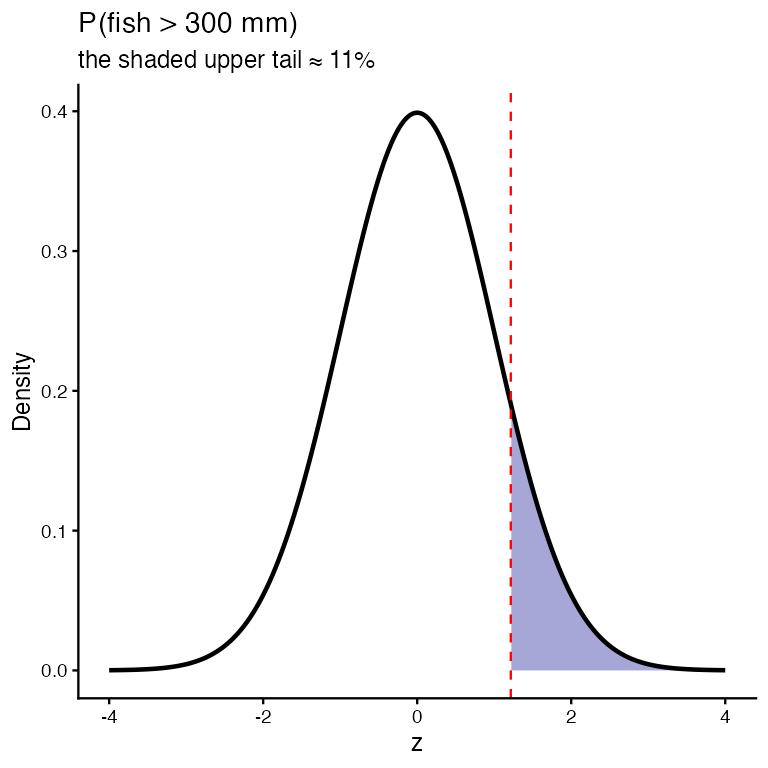
Worked example — how rare is a 300 mm grayling?
Step 1 — standardize.
\(z = \frac{300 - 265.61}{28.3} = 1.22\)
Step 2 — look it up. Row 1.2, column 0.02 → 0.8888
Step 3 — read it as biology.
- 88.9% of I3 fish are shorter than 300 mm
- 100 − 88.9 = 11.1% are longer
Catch 100 fish in I3 and about 11 should beat 300 mm.
Same answer, in R — no table:
Running it backwards — qnorm
The table question can be asked the other way round, and in fisheries it usually is:
We had a length and wanted a probability. Now we have a probability and want a length.
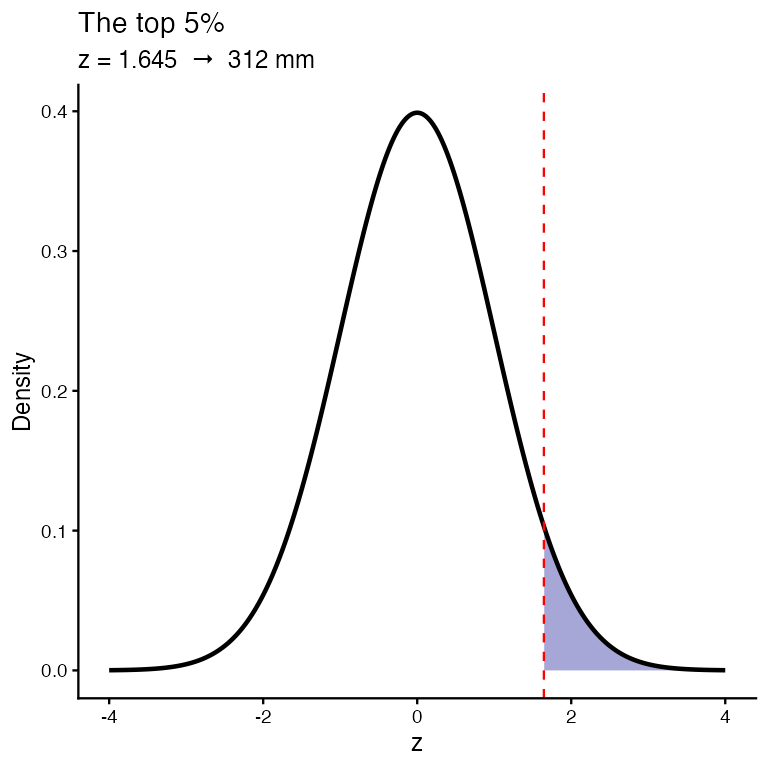
“How big must a grayling be to land in the top 5%?” — the trophy-fish question, and the size-limit question.
qnorm(0.95)= 1.645 — the z with 5% above it- Back to millimetres: \(x = \mu + z\sigma\)
[1] 312.2Only 5% of I3 fish should exceed 312.2 mm.
Every number on this slide assumed the fish are normal. Do we know that?
Shapiro-Wilk — and its backwards logic
The Shapiro-Wilk test asks one question, and its hypotheses run opposite to what you expect:
- H₀: the data ARE normal
- Hₐ: the data are NOT normal
So:
- p > 0.05 → no evidence against normal → carry on
- p < 0.05 → evidence of non-normality → be careful
A small p-value here is bad news, not a result. That reversal is why this test gets misread every semester.
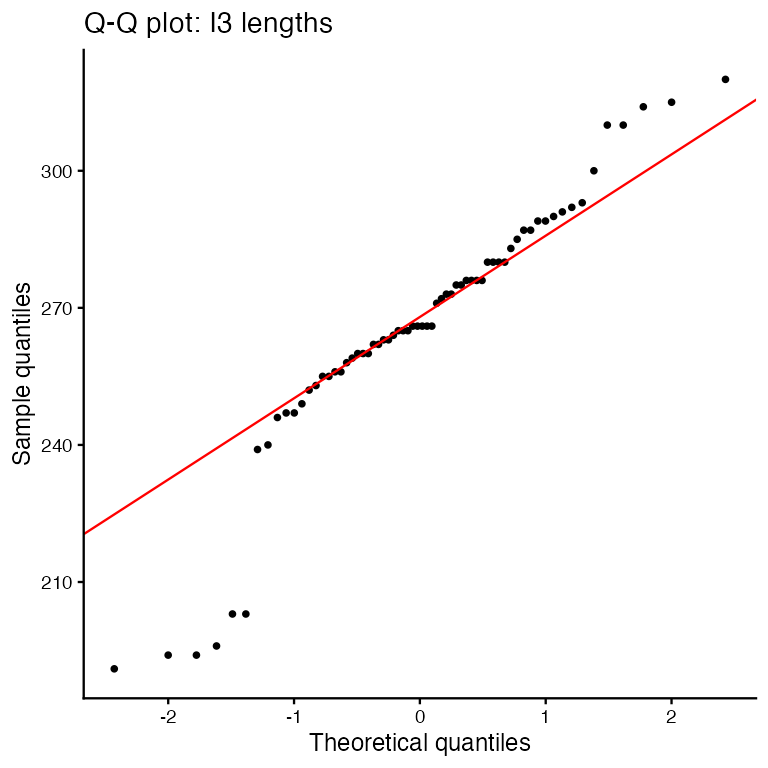
Two cautions: with large n it flags departures too small to matter; with small n it misses ones that matter. Always read the Q-Q plot too — points on the line = normal.
So how wrong were we?
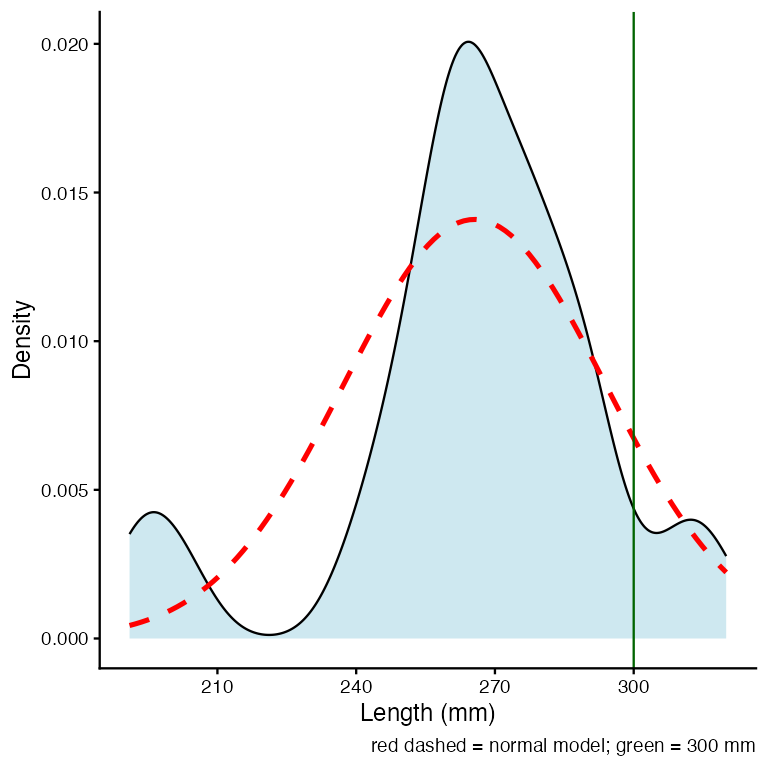
p = 0.0002. The I3 fish are not normal. Every probability in Part 2 assumed they were — so let’s audit them against the fish themselves.
| normal theory | actual data | |
|---|---|---|
| within ±1 SD | 68% | 81.8% |
| 95th percentile | 312.2 mm | 310 mm |
| P(fish > 300 mm) | 11.2% | 7.6% |
The centre is fine. The tail is off by a third.
And the tail is exactly where inference lives — critical values, rejection regions, p-values all sit out in the tails.
This is why we check assumptions before trusting a p-value.
What a confidence interval actually is
We have one sample and one mean, 265.6 mm. The true μ is some other number we will never see. A confidence interval is our honest statement of how close we probably are.
The recipe: \(\bar{y} \pm (\text{critical value}) \times SE\)
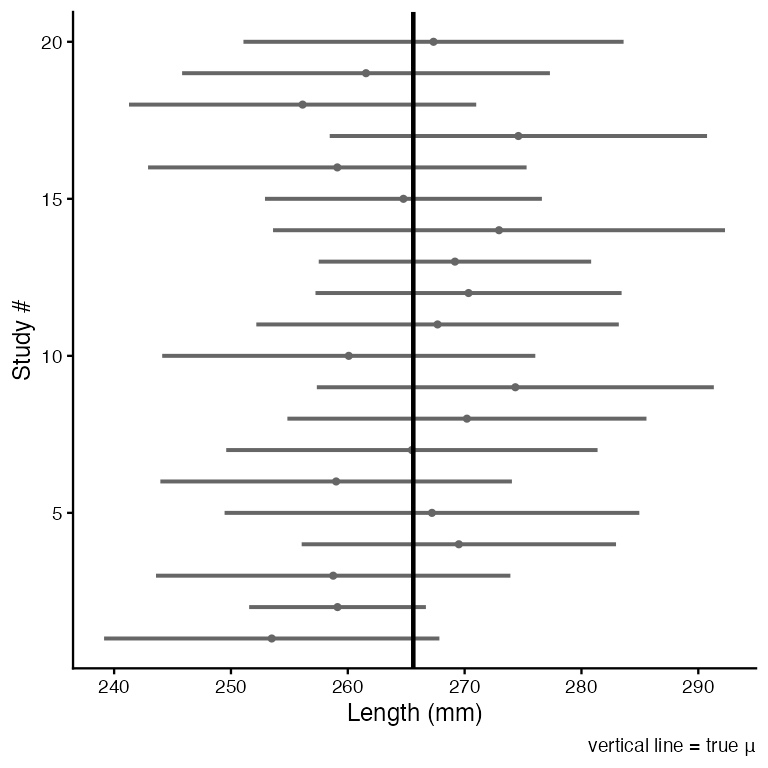
What “95%” means: repeat the whole study many times, build an interval each time, and 95% of those intervals will contain μ. The figure shows 20 such studies — one misses.
Warning
The interpretation everyone gets wrong
❌ “There is a 95% chance μ is in my interval.”
✅ “95% of intervals built this way capture μ.”
μ is a fixed number — it is not moving around. The interval is what is random. Yours either caught μ or it didn’t; you don’t get to know which.
If we knew σ, we would use z
When the population σ is genuinely known, the critical value comes straight off the standard normal:
\(CI = \bar{y} \pm 1.96 \cdot \frac{\sigma}{\sqrt{n}}\)
- 1.96 because 95% of the standard normal lies within ±1.96
- 90% CI → 1.645 · 99% CI → 2.576 · all from
qnorm()
Wider confidence costs a wider interval. You cannot be more certain and more precise at the same time — only a bigger n buys you both.
But we never know σ — so z is too confident
Look again at that formula. It needs σ, the population standard deviation. We have never once had it.
What we actually have is s, computed from our 66 fish. And s is itself an estimate — a different sample gives a different s.
Two sources of uncertainty, not one:
- the mean wobbles from sample to sample
- our estimate of the spread also wobbles
Using 1.96 accounts for the first and ignores the second. Intervals come out too narrow and we claim more precision than we earned.
Gosset hit exactly this at Guinness — tiny barley samples, σ never known. His fix: use a curve with fatter tails, so the critical value is bigger and the interval honest.
That curve is Student’s t.
The t-distribution
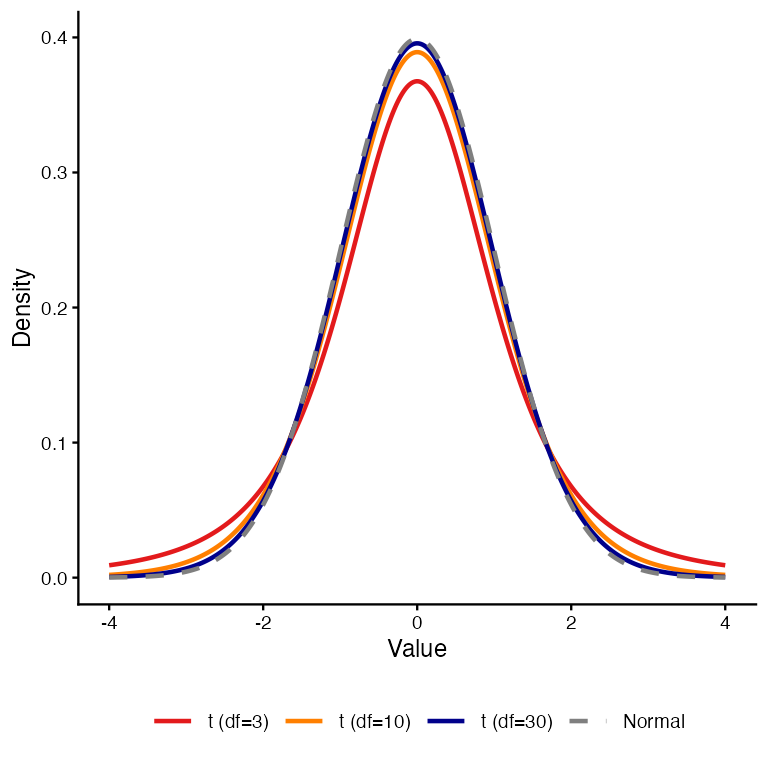
Same bell shape as the normal, but heavier in the tails — that extra thickness is the price of estimating σ.
- Shape set by degrees of freedom, df = n − 1
- Small df → very heavy tails → large critical values
- df grows → t creeps toward the normal
- Past n ≈ 30 they agree to about two decimals — which is where the “n > 30” rule of thumb came from
Important
The rule that matters: whenever σ is estimated from the sample, use t — at any sample size. “n > 30, use z” is a convenience from the era of paper tables, not a statistical law. R uses t always.
Reading the t-table
\(CI = \bar{y} \pm t \cdot \frac{s}{\sqrt{n}}\)
Only the multiplier changed: t in place of 1.96.
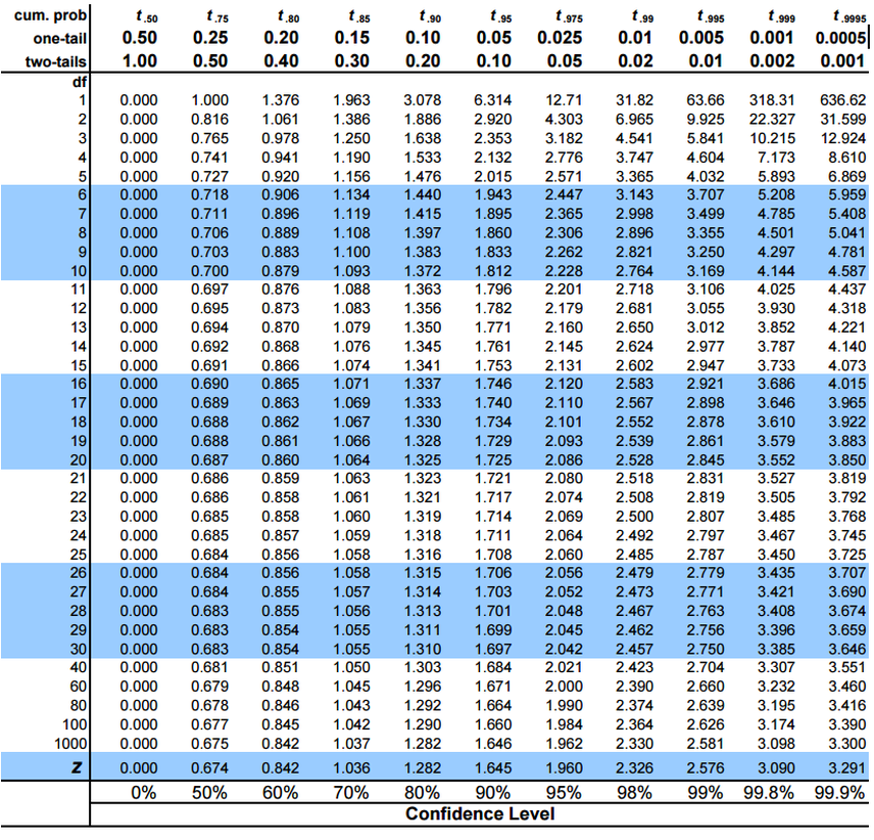
- Rows = degrees of freedom (n − 1)
- Columns = probability, with two header rows: one-tail and two-tail
- A CI is always two-tailed — it has two ends. Use the two-tail column
The bottom row (df = ∞) is 1.96: the t-table contains the z-table.
Worked CI — by table and by R
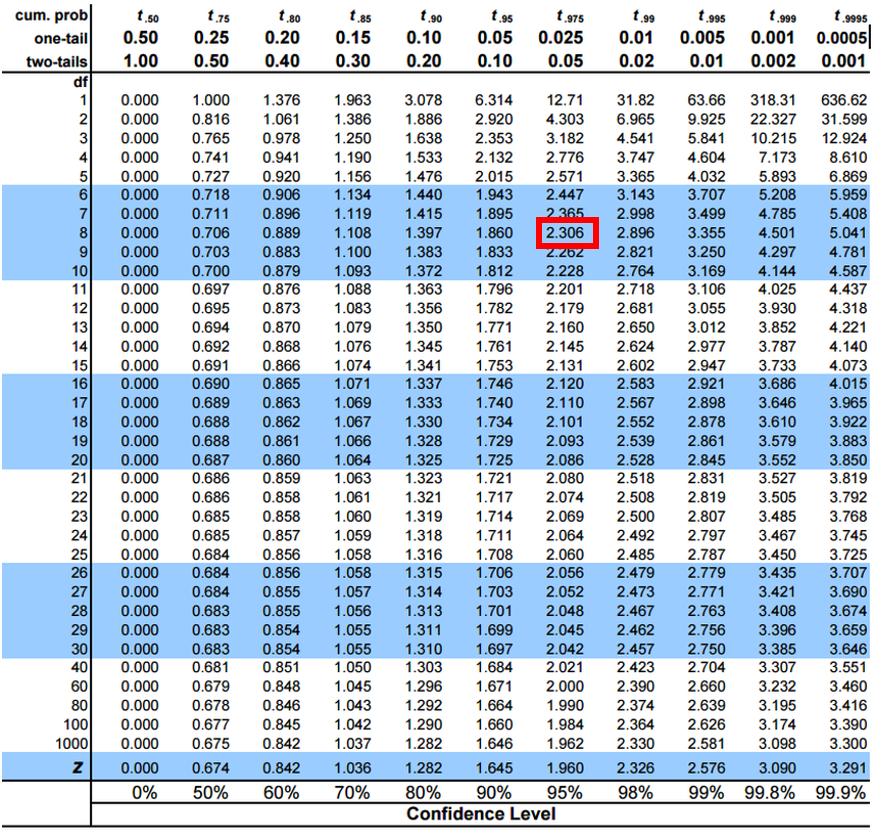
A sample of 9 fish: mean = 272.8, s = 37.81
- df = 9 − 1 = 8
- Two-tail 0.05 column, row 8 → t = 2.306
- SE = 37.81 / √9 = 12.60
- Margin = 2.306 × 12.60 = 29.06
- CI = 272.8 ± 29.06 = 243.7 to 301.9 mm
“The 95% CI for mean length is 243.7–301.9 mm.”
Had we wrongly used 1.96, we’d have reported ±24.7 — an interval 15% too narrow, claiming precision we never had.
The logic
A confidence interval asks where is μ? A hypothesis test asks is μ equal to some specific value? Same machinery, different question.
- H₀ — the boring claim: no effect, no difference
- Hₐ — what we suspect instead
- Assume H₀ is true and ask: how likely is data like ours?
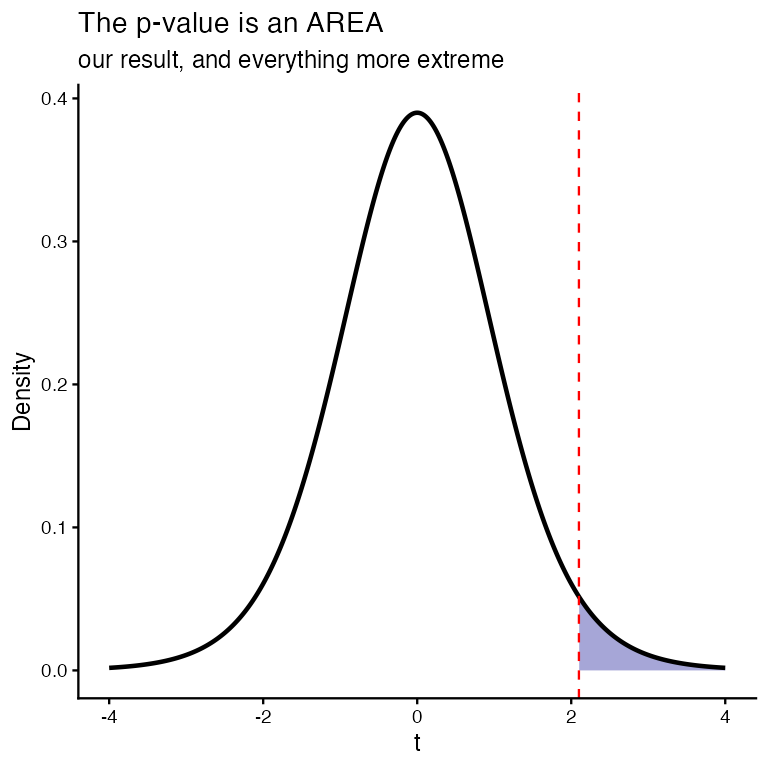
- p-value — probability of our result, or more extreme, if H₀ is true
- α — how rare is rare enough, set before looking. Usually 0.05
- Decide — p < α → reject H₀
\(t = \frac{\bar{y} - \mu_0}{s / \sqrt{n}}\) — how many SEs is our mean from the claim?
One-tailed: all of α at one end
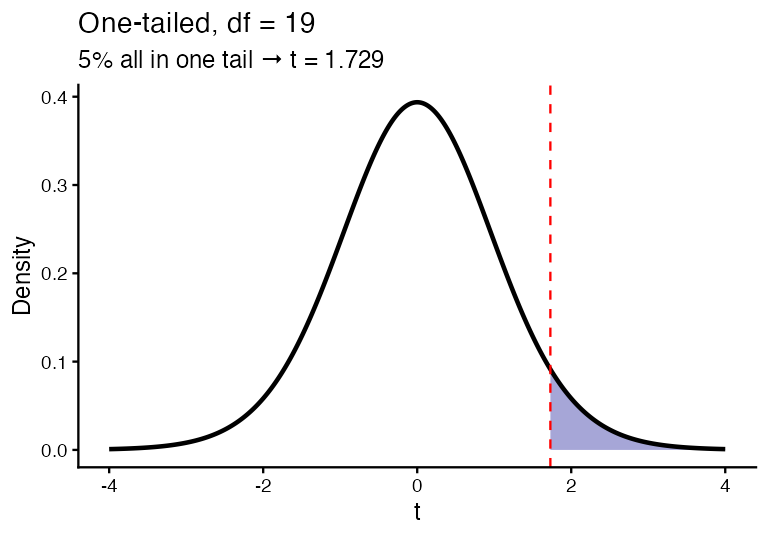
Use when the question has a direction: are these fish longer than 285 mm? A shorter result would not interest us — it goes with H₀.
- H₀: μ ≤ 285 · Hₐ: μ > 285
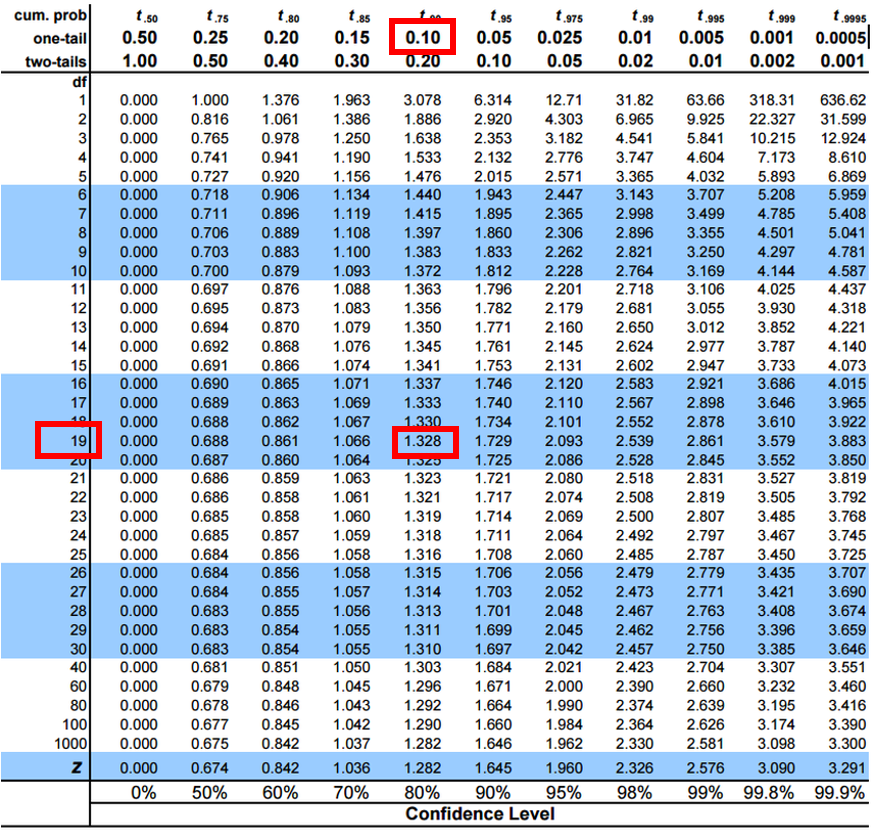
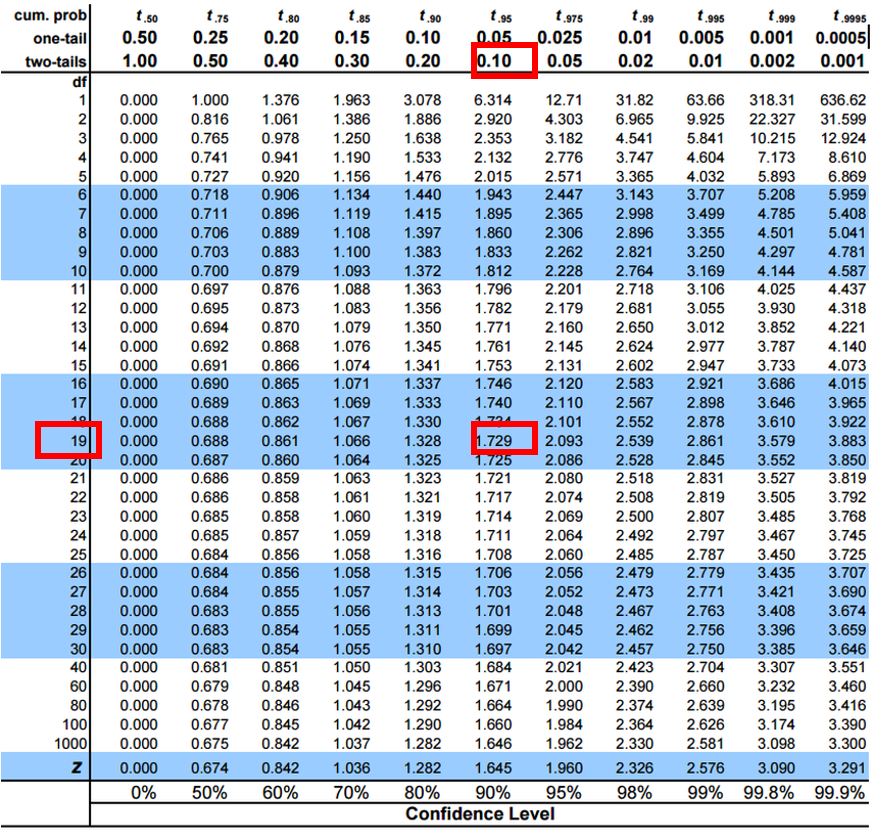
- n = 20, so df = 19
- All 5% sits in the upper tail
- t-table, one-tail 0.05, row 19 → t = 1.729
Reject H₀ only if our t exceeds +1.729.
Two-tailed: α split between both ends
Use when either direction would matter: do these fish differ from 285 mm? Longer or shorter, we want to know.
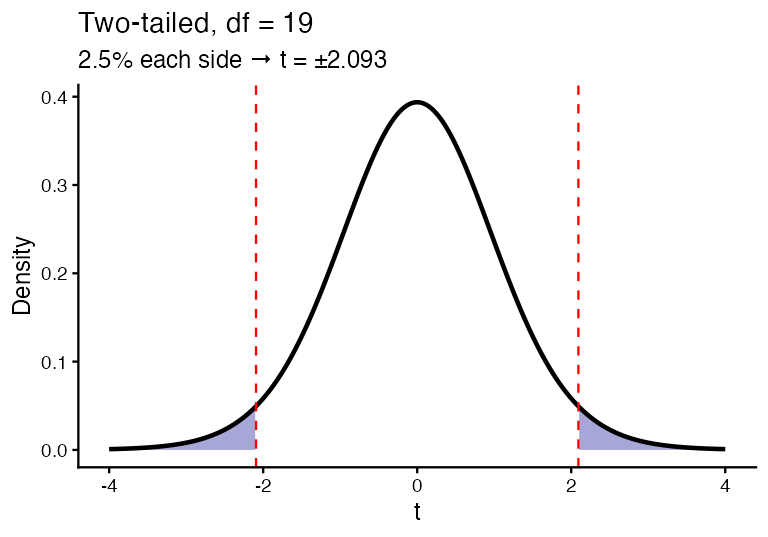
- H₀: μ = 285 · Hₐ: μ ≠ 285
- Same df = 19, same total α = 0.05
- But now 2.5% in each tail
- t-table, two-tail 0.05, row 19 → t = 2.093
Important
Same α, same df, bigger critical value (2.093 > 1.729) — splitting α pushes each cutoff further out, so a two-tailed test is harder to pass.
Pick your tails from the question, before seeing the data. When in doubt, two-tailed — it is also R’s default.
What a p-value is not
It is: the probability of data like ours if H₀ were true.
It is not:
- the probability that H₀ is true
- the probability the result is due to chance
- a measure of how big the effect is
Small p means detectable, not large. With n = 168, a biologically meaningless 2 mm difference can return p = 10⁻¹⁶.
So, every time:
- report p < 0.001, not
p = 1.2e-16 - report the effect size — the difference in millimetres
- report the CI — it shows size and uncertainty in one line
- significant ≠ important. That call is biology, not arithmetic