Lecture 04 — GGPlot II
New data, safe zooming, distributions, themes, and patchwork
2026-10-01
The Same Simple XY Plot — On New Data
Note
🔮 Predict first: flipper length and body mass should move together — longer flippers, heavier birds. Will three species separate into three clouds, or overlap into one?
# The exact same recipe you used on leaf_df ------------
penguins_df %>%
  ggplot(aes(x = flipper_length_mm, y = body_mass_g,
             color = species)) +
  geom_point(alpha = 0.7, size = 2) +
  labs(
    title = "Body Mass vs. Flipper Length",
    x = "Flipper Length (mm)",
    y = "Body Mass (g)",
    color = "Species"
  ) +
  theme_minimal()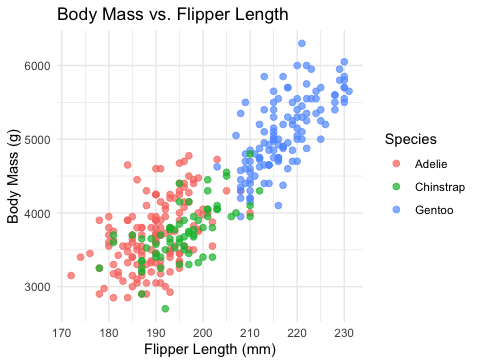
- Same
aes()+geom_point()+labs()+theme_minimal()you already typed for leaves - The dataset changed, the recipe didn’t — that’s the point
- Nothing here is new syntax; it’s proof you can already do this on any data
The Same Simple Categorical Plot — On New Data
# boxplot + jitter, exactly like the leaf_df pattern ---
penguins_df %>%
  ggplot(aes(x = species, y = body_mass_g, fill = species)) +
  geom_boxplot(alpha = 0.6, outlier.shape = NA) +
  geom_jitter(width = 0.15, alpha = 0.4) +
  labs(x = "Species", y = "Body Mass (g)",
       title = "Body Mass by Species") +
  theme_minimal() +
  theme(legend.position = "none")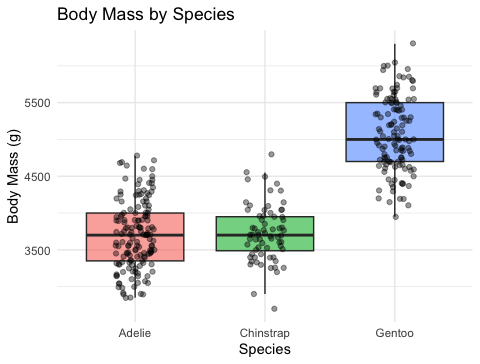
Tip
💡 Where would you find a dataset like this on your own?
library(palmerpenguins)orlibrary(FSA)(fish data, Derek Ogle) — real data bundled inside an R package, zero downloading- Kaggle — search “UFO sightings” or Kaggle — search “Bigfoot sightings” — download a
.csv, load it withread_csv()like any other file
Both a simple XY numeric plot and a simple categorical plot (like today’s two) work on almost any tidy dataset you find.
coord_cartesian() — Zoom the View, Keep the Data
# coord_cartesian() zooms the VIEW, keeps all the data -
penguins_df %>%
  ggplot(aes(x = species, y = body_mass_g, fill = species)) +
  geom_boxplot(alpha = 0.6, outlier.shape = NA) +
  coord_cartesian(ylim = c(3000, 5000)) +
  labs(x = "Species", y = "Body Mass (g)",
       title = "Zoomed with coord_cartesian()") +
  theme_minimal() +
  theme(legend.position = "none")
- Zooms the view — every penguin still contributes to each box’s median and quartiles
- The window just crops what you can see afterward
- This is the one to reach for whenever you just want a closer look
The Trap — ylim() / scale_y_continuous(limits = ) Delete Rows First
Note
🔮 Predict first: Gentoo penguins run heavier than the other two species — many sit above 5000 g. If we drop every penguin outside 3000–5000 g before drawing the boxes, what happens to the Gentoo box specifically?
# ylim() DELETES rows outside the range first ----------
penguins_df %>%
  ggplot(aes(x = species, y = body_mass_g, fill = species)) +
  geom_boxplot(alpha = 0.6, outlier.shape = NA) +
  ylim(3000, 5000) +
  labs(x = "Species", y = "Body Mass (g)",
       title = "ylim() — boxes recomputed on fewer penguins") +
  theme_minimal() +
  theme(legend.position = "none")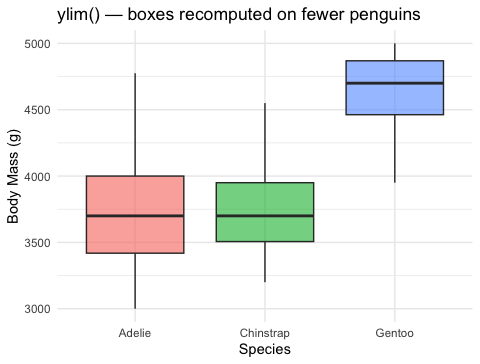
Warning
⚠️ Watch out!
ylim() — and its long form scale_y_continuous(limits = c(3000, 5000)) — silently delete every row outside the range before anything is computed. Compare the Gentoo box above to the coord_cartesian() version: same window, different box.
Rule: zoom with coord_cartesian(). Only use ylim() / scale_y_continuous(limits = ) when you actually want those rows gone from the analysis.
geom_histogram() — Bars of Counts
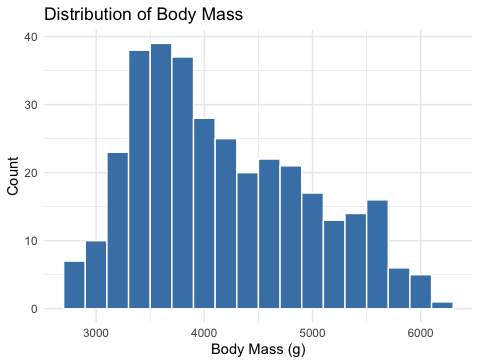
binwidthsets the width of each bar in the units ofx— here, 200 g per bin- Too narrow → noisy, spiky bars. Too wide → real structure gets smoothed away
- Try a few
binwidthvalues before settling on one
geom_density() — a Smooth Curve Instead of Bars
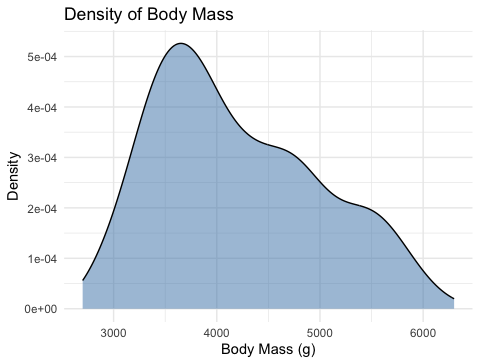
- Same variable, same shape — a density curve is a smoothed histogram, area under the curve sums to 1
- The y-axis is no longer a count — it’s a density, which is why the numbers look small
- 📖 Whitlock & Schluter, Ch. 2 — Displaying Data
Tip
Coming soon: in the Summary Statistics lecture we’ll come back to this exact curve and shade in the 95% range underneath it. Today, just get comfortable building both plot types.
source() a Theme File Instead of Repeating theme()
# source() loads functions from another .R file -------
source("themes/r_themes_for_3_sizes.R")

penguins_df %>%
  ggplot(aes(x = species, y = body_mass_g, fill = species)) +
  geom_boxplot(alpha = 0.6, outlier.shape = NA) +
  labs(x = "Species", y = "Body Mass (g)",
       title = "Body Mass by Species") +
  theme_regular() +
  theme(legend.position = "none")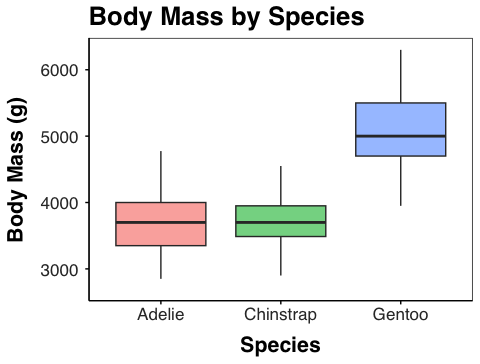
source("themes/r_themes_for_3_sizes.R")runs that file once and loadstheme_small(),theme_regular(),theme_large()into your session- You don’t need to understand every line inside the file today — just how to call it
- Pick the size that matches where the figure is going: slides/report →
theme_regular()
Tweaking Fonts and Colors on Top
# theme() and scale_fill_manual() still work as usual --
penguins_df %>%
  ggplot(aes(x = species, y = body_mass_g, fill = species)) +
  geom_boxplot(alpha = 0.6, outlier.shape = NA) +
  scale_fill_manual(values = c(
    "Adelie" = "darkorange", "Chinstrap" = "purple",
    "Gentoo" = "cyan4"
  )) +
  labs(x = "Species", y = "Body Mass (g)",
       title = "Body Mass by Species") +
  theme_regular() +
  theme(
    legend.position = "none",
    plot.title = element_text(size = rel(1.4), face = "bold")
  )
- A sourced theme is still just a
theme()call —+ theme(...)after it overrides individual pieces, same as any built-in theme scale_fill_manual()still controls colors; the theme controls everything else (fonts, lines, margins)
Note
✅ Key idea
One theme file, sourced at the top of every script, keeps every figure in a project looking consistent — change the file once, every plot updates.
patchwork — Two Plots, One Figure
library(patchwork) # combine ggplot objects with + and /

xy_plot <- penguins_df %>%
  ggplot(aes(x = flipper_length_mm, y = body_mass_g,
             color = species)) +
  geom_point(alpha = 0.7) +
  labs(x = "Flipper Length (mm)", y = "Body Mass (g)",
       color = "Species") +
  theme_regular()

box_plot <- penguins_df %>%
  ggplot(aes(x = species, y = body_mass_g, fill = species)) +
  geom_boxplot(alpha = 0.6, outlier.shape = NA) +
  labs(x = "Species", y = "Body Mass (g)") +
  theme_regular() +
  theme(legend.position = "none")

xy_plot + box_plot +
  plot_annotation(
    title = "Penguin Body Mass, Two Ways",
    tag_levels = "A"
  )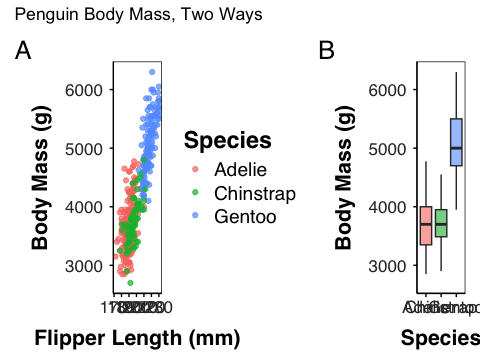
- Each panel is an ordinary saved ggplot object — build them separately first, exactly like you already do
+places twopatchwork-ready plots side by side;/stacks themplot_annotation()adds one title and A/B/C tags across the whole combined figure, not any single panel