Activity 15 — Wide, Long, and Wild: Pivoting Real Data
Reshaping Lake Superior ice cover with pivot_longer() and pivot_wider()
Hands-on companion to the pivoting lecture. Students read NOAA’s messy wide ice-cover file straight from the web, pivot it long, fix winters that cross the new year, summarize, pivot back wider, regress monthly ice on year, rebuild NOAA’s spaghetti plot, and model the trend in maximum ice cover. Students hand in the finished script.
In-class Activity 15: Pivoting Lake Superior Ice Data
Today’s Objectives
- Read a messy, wide government text file directly from the web
- Say why wide data breaks
ggplot()andgroup_by() - Use
pivot_longer()to make it tidy — andpivot_wider()to make a summary table - Fix a real-world date wrinkle: winters that cross the new year
- Regress one month’s ice cover on
yearto get a slope - Rebuild NOAA’s “spaghetti plot” of every ice season
- Use
slice_max()to pull each winter’s peak ice cover - Fit
lm()to ask whether maximum ice cover is declining - Flip the summary table back to long and compare every month’s slope at once
- If there is time: join in Duluth’s monthly temperature and regress ice on temp — this month’s and last month’s
- Repeat the whole thing on a different Great Lake, for homework
- Skeleton script:
15_ice_pivot_skeleton.R→ save it asscripts/15_ice_pivot.R. - No data file. The skeleton reads a live NOAA text file off the web — you need an internet connection.
- All of today’s code is right here in this activity. Type it into your script as we go and run it chunk by chunk. The skeleton has the import, the cleaning, the pivot to the wide summary table, and the regression already written — Part 10 is the one blank you fill in yourself.
- The Q boxes are things to think about, not inline homework. Read them, talk them over, answer them in your head. They are there for your benefit — you do not have to type answers into the script, and they are not graded.
- The homework at the bottom runs the whole workflow on a different Great Lake — that part you write, and that part is graded.
- Hand in
scripts/15_ice_pivot.R. Run it top to bottom (Ctrl/Cmd + Shift + Enter) first — it must run with no errors.
Pivoting is easy to fake your way through by staring at dim() after the fact. Before each pivot, say out loud the shape you expect — how many rows, how many columns — then run it. A wrong prediction points straight at the argument you misunderstood: cols, names_to, or values_to.
Keep the plots plain today — no labels, colors, or themes except where the code already has them. The goal is to read them.
invisible(NULL) lines in the skeleton
Every chunk ends with invisible(NULL). It is a bumper. Press Ctrl/Cmd + Enter on a chunk’s last real line and your cursor jumps to the next line that has code on it — without the bumper, that is the next chunk, way down past the next heading. With it, the cursor stops right there and you keep your place. It does nothing and prints nothing.
🧩 Chunk 1 — Why wide data is a problem (after lecture Chunk 1)
Parts 1–2: read NOAA’s raw file and inspect its wide shape.
Part 1 · Load libraries and read the raw file
▶ Run this:
# Load libraries ---------------------------------------
library(tidyverse)   # dplyr + tidyr + ggplot2 + stringr
library(lubridate)   # ymd(), month(), update()
▶ Run this:
# Read NOAA's messy text file straight off the web -----
url <- "https://www.glerl.noaa.gov/data/ice/glicd/daily/sup.txt"

ice_raw <- read.table(
  url,
  header = TRUE,
  na.strings = c("-999", "-99.00", "NA")
) %>%
  rownames_to_column(var = "date") %>%
  as_tibble()

head(ice_raw)
⚠️ Watch out! This file is space-separated, not comma-separated — that is why it needs
read.table()and notread_csv(). The day labels (Nov-10…) arrive as row names, sorownames_to_column()turns them into a realdatecolumn.
✏️ Q1: Why can’t read_csv() open this file?
Part 2 · Inspect the wide shape
▶ Run this:
# How wide is wide? ------------------------------------
dim(ice_raw)

names(ice_raw)
✏️ Q2: R glued an X onto the front of every year column — X1973. Why?
✏️ Q3: “Year” is hiding as 50-odd column names, not as values in a column. Why does that make ggplot(aes(x = year)) and group_by(year) impossible right now?
🧩 Chunk 2 — Reshape with pivot_longer & fix dates (after lecture Chunk 2)
Parts 3–4: pivot the data long, then fix the winters that cross the new year.
Part 3 · Pivot from wide to long
🔮 Predict first:
ice_rawis about 209 rows × 55 columns. Afterpivot_longer()collapses every year column, how many columns will the result have, and roughly how many rows?
▶ Run this:
# Collapse every year column into year + ice_cover -----
ice_long <- ice_raw %>%
  pivot_longer(
    cols = -date,
    names_to = "year",
    names_prefix = "X",
    values_to = "ice_cover"
  ) %>%
  arrange(year, date)

dim(ice_long)

head(ice_long)
Four arguments do all the work: cols = -date pivots everything except date, names_to says where the old column names go, names_prefix strips the X off the front, and values_to names the column the cell values land in.
✏️ Q4: What does names_prefix = "X" do? What would the year column hold without it?
Part 4 · Fix winters that cross the new year
An ice season runs Nov → May, but NOAA labels the whole season by the year it ends in. So Nov-10 under column 1974 really happened in November 1973.
▶ Run this:
# Nov/Dec belong to the PREVIOUS calendar year ---------
ice_clean <- ice_long %>%
  mutate(
    year = as.numeric(year),
    calendar_year = if_else(
      str_starts(date, "Nov|Dec"),
      year - 1,
      year
    ),
    full_date = ymd(paste(calendar_year, date, sep = "-")),
    month = month(full_date, label = TRUE)
  ) %>%
  drop_na(ice_cover, full_date)

dim(ice_clean)

head(ice_clean)
⚠️ Watch out!
ymd()will warn that about 41 dates “failed to parse”. Those areFeb-29in years that had no February 29th.drop_na()removes them, which is exactly right — there was no such day.
✏️ Q5: Why do we subtract 1 from year for November and December dates?
🧩 Chunk 3 — Summarize & pivot back wider (after lecture Chunk 3)
Parts 5–7: summarize the tidy data, rebuild a readable table with
pivot_wider(), and regress one month on year.
Part 5 · Summarize now that we’re long
▶ Run this:
# Mean ice cover for every year-month ------------------
monthly_avg <- ice_clean %>%
  group_by(year, month) %>%
  summarize(
    mean_ice = mean(ice_cover, na.rm = TRUE),
    .groups = "drop"
  )

head(monthly_avg)
✏️ Q6: This is the same group_by() pattern you used in Summary Statistics. Why was it impossible to run on ice_raw?
Part 6 · Pivot back to a wide summary table
🔮 Predict first:
pivot_wider()will make one row per year and one column per month. Roughly how many rows (years) and columns (months + 1)?
▶ Run this:
# One row per year, one column per month ---------------
ice_pivot_table <- ice_clean %>%
  pivot_wider(
    id_cols = year,
    names_from = month,
    values_from = ice_cover,
    values_fn = mean
  ) %>%
  arrange(year)

ice_pivot_table
⚠️ Watch out! The month columns come out in the order the months first appear in the data, not in calendar order —
Apr,Dec,Feb,Jan… That is normal forpivot_wider(), and it is why long data is better for computing.
✏️ Q7: Why is there a Jun column at all, and why is it almost all NA?
✏️ Q8: When would you reach for pivot_longer(), and when for pivot_wider()? One sentence each.
💡 Key idea: long is for computing —
group_by,summarize,ggplot. Wide is for reading — a table a human scans. The same data, shaped for two different audiences.
Part 7 · Regress one month’s ice cover on year
February is usually Lake Superior’s iciest month. Now that the wide table has a Feb column, one month’s whole 50-year history is a single column — so a regression on year is one line of code.
🔮 Predict first: is February ice cover declining, flat, or rising? Will the slope be significant at α = 0.05?
▶ Run this:
# February ice cover predicted by year -----------------
feb_model <- lm(Feb ~ year, data = ice_pivot_table)

summary(feb_model)
▶ Run this:
# Plot it ----------------------------------------------
ice_pivot_table %>%
  ggplot(aes(x = year, y = Feb)) +
  geom_point() +
  geom_smooth(method = "lm")
✏️ Q9: Slope (% per year), p, and R² for February. Significant at α = 0.05?
✏️ Q10: Try Mar and Apr too. Does every month have the same slope?
💡 Key idea: this works because the wide table put one month in one column. Doing it month by month gets old fast — in Part 10 you flip the table back to long and get every month’s slope in one shot.
🧩 Chunk 4 — Visualize & model the trend (after lecture Chunk 4)
Parts 8–11: rebuild NOAA’s spaghetti plot, pull each year’s peak, model the trend, flip the table back to long, and — if there is time — join in Duluth’s temperature.
Part 8 · Rebuild NOAA’s spaghetti plot
This is the long one. Type it, run it, and read it — do not worry about memorizing it.
The one idea worth carrying away: to overlay 50 winters on one axis, every date is forced onto a single fake year — October onward becomes 1999, January onward becomes 2000 — so the x-axis runs November → June once.
▶ Run this:
# Force every date onto one fake shared year -----------
ice_plot_data <- ice_clean %>%
  mutate(
    plot_date = if_else(
      month(full_date) >= 10,
      update(full_date, year = 1999),
      update(full_date, year = 2000)
    )
  )

# The historical average for each day-of-winter --------
historical_avg <- ice_plot_data %>%
  group_by(plot_date) %>%
  summarize(avg_ice = mean(ice_cover, na.rm = TRUE))

current_yr <- max(ice_plot_data$year)
past_years <- ice_plot_data %>% filter(year < current_yr)
current_year_data <- ice_plot_data %>% filter(year == current_yr)
▶ Run this:
# Three layers, three geom_line() calls ----------------
ice_spaghetti_plot <- ggplot() +
  geom_line(
    data = past_years,
    aes(x = plot_date, y = ice_cover, group = year),
    color = "blue",
    alpha = 0.15
  ) +
  geom_line(
    data = historical_avg,
    aes(x = plot_date, y = avg_ice),
    color = "red",
    linewidth = 1.2
  ) +
  geom_line(
    data = current_year_data,
    aes(x = plot_date, y = ice_cover),
    color = "black",
    linewidth = 1.2
  ) +
  scale_x_date(date_labels = "%b", date_breaks = "1 month") +
  labs(
    title = "Lake Superior Average Ice Cover",
    subtitle = paste("Comparing", current_yr, "to Historical Data"),
    x = NULL,
    y = "Ice Cover (%)"
  ) +
  theme_bw()

ice_spaghetti_plot
✏️ Q11: Open NOAA’s published plot at https://www.glerl.noaa.gov/data/ice/spaghetti/sup_ice_compare.png. What does the red line represent, and why is the current year drawn last?
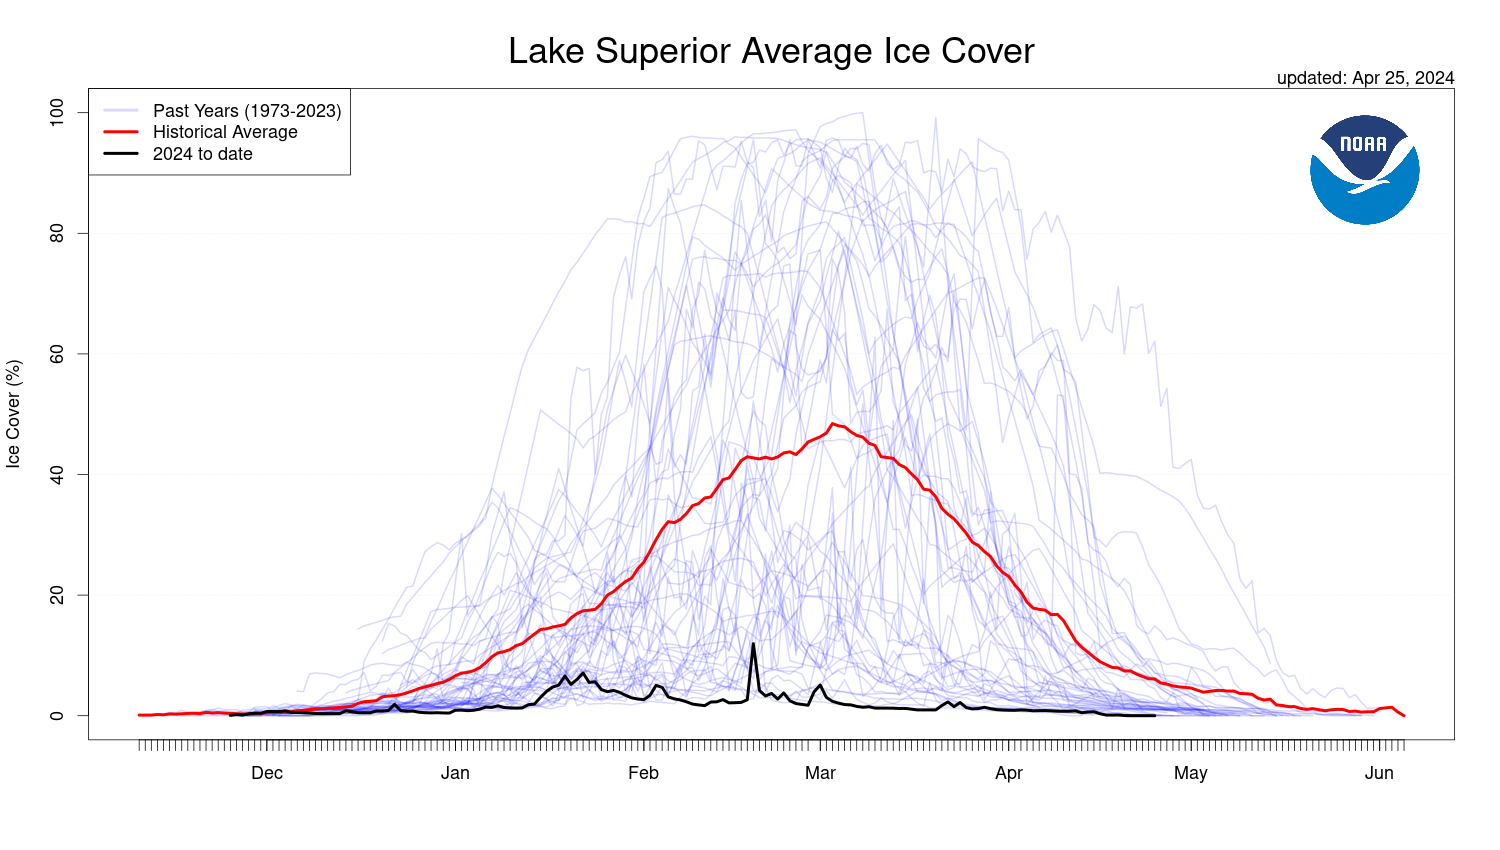
✏️ Q12: The thin blue lines use group = year. Take it out in your head — what would the plot look like instead?
Part 9 · Each winter’s peak ice, and the trend in it
🔮 Predict first:
slice_max()keeps the single highest ice-cover day per year. How many rows will the result have?
▶ Run this:
# The single iciest day of each winter -----------------
max_ice_per_year <- ice_clean %>%
  group_by(year) %>%
  slice_max(order_by = ice_cover, n = 1, with_ties = FALSE)

nrow(max_ice_per_year)

max_ice_per_year %>%
  arrange(ice_cover) %>%
  select(year, date, ice_cover)
✏️ Q13: Which winters had the lowest and the highest peak ice?
✏️ Q14: Look at the date of each year’s peak. Does it move around much from winter to winter?
🔮 Predict first: over 50+ years, is maximum ice cover declining, flat, or rising? And given the huge year-to-year scatter, will the slope come out significant at α = 0.05?
▶ Run this:
# Maximum ice cover predicted by year ------------------
max_ice_model <- lm(ice_cover ~ year, data = max_ice_per_year)

summary(max_ice_model)
▶ Run this:
# Plot the yearly peaks with a trend line --------------
max_ice_per_year %>%
  ggplot(aes(x = year, y = ice_cover)) +
  geom_point() +
  geom_smooth(method = "lm")
✏️ Q15: The slope is significant and the R² is small — around 0.13. What is each number telling you, and why are they not in conflict?
✏️ Q16: One sentence: is Lake Superior’s peak ice cover changing, and how confident are you given the scatter?
💡 Key idea: a real trend can be significant and still explain only a slice of the variation. Ice cover swings wildly with ENSO and the polar vortex; the long-term decline is a quiet signal underneath very loud year-to-year noise. Reporting the slope without the R² — or the R² without the slope — tells only half of that.
Part 10 · Flip the wide table back to long (you write this one)
This is the one chunk the skeleton leaves blank — this is where we left off in class. You have the pattern from Part 3; the only thing that changes is which table you pivot.
In Part 7 you ran one regression per month, by hand, one column at a time. There is a better way: flip ice_pivot_table back to long and every month’s slope comes out of a single group_by().
🔮 Predict first:
ice_pivot_tableis about 54 rows × 9 columns. Pivot all the month columns long — how many rows before you drop theNAs?
▶ Type this yourself:
# Wide summary table -> long again ---------------------
monthly_long <- ice_pivot_table %>%
  pivot_longer(
    cols = -year,
    names_to = "month",
    values_to = "mean_ice"
  ) %>%
  drop_na(mean_ice) %>%
  filter(month %in% c("Dec", "Jan", "Feb", "Mar", "Apr"))

dim(monthly_long)

head(monthly_long)
The filter() drops Nov, May, and Jun — months with only a handful of years of data, which is not enough to fit a line to.
▶ Type this yourself:
# Every month's slope, in one shot ---------------------
monthly_slopes <- monthly_long %>%
  group_by(month) %>%
  summarize(
    n_years = n(),
    slope = coef(lm(mean_ice ~ year))[2]
  )

monthly_slopes
▶ Type this yourself:
# One panel per month ----------------------------------
monthly_long %>%
  ggplot(aes(x = year, y = mean_ice)) +
  geom_point() +
  geom_smooth(method = "lm") +
  facet_wrap(~ month)
✏️ Q17: Check your Feb slope against the one from Part 7. They should match — same data, same model, different shape.
✏️ Q18: Which month is losing ice fastest, and which slowest? Why might mid-winter change faster than the shoulder months?
💡 Key idea: you went wide → long → wide → long in one script, and nothing was lost on any trip. Shape is not information; shape is just whichever form the next tool needs. Wide to read it, long to compute on it.
Part 11 · If there is time — bring in Duluth’s temperature
Ice cover is the response to something: cold. So far every model has used year as the predictor, which is a stand-in for “whatever is changing.” Now use the actual driver.
You need the temperature data on the same scale as the ice data — one value per calendar month — and then a left_join() to put the two together. (Joins are their own lecture when we come back from break. Here it is as a preview.)
▶ Run this:
# Two more libraries -----------------------------------
library(janitor)   # clean_names()
library(GSODR)     # NOAA station data
You installed GSODR back in Activity 12 — no need to install it again. Loading it prints a notice that GSOD retired in Aug 2025; that is expected, the archive still downloads.
▶ Run this:
# Mean ice cover for each calendar month ---------------
ice_monthly <- ice_clean %>%
  mutate(month_date = floor_date(full_date, "month")) %>%
  group_by(month_date) %>%
  summarize(mean_ice = mean(ice_cover, na.rm = TRUE),
            .groups = "drop")

ice_monthly
floor_date() knocks every date back to the first of its month, so every day in February 1979 becomes 1979-02-01. That gives you one row per month, with a real date as the key to join on.
⚠️ Watch out! Group on
month_date, not onyearandmonth. Rememberyearis the season-end year — a December belongs to the season labeled with the next year.floor_date(full_date)uses the real calendar date, which is what the weather data will be keyed on.
▶ Run this:
# Duluth daily weather, same years as the ice record ---
duluth_df <- get_GSOD(years = 1973:2025,
                      station = "727450-14913") %>%
  clean_names()

dim(duluth_df)
This takes a minute — it is 50+ years of daily records.
▶ Run this:
# Monthly mean temp, plus the PREVIOUS month's temp ----
dlh_month <- duluth_df %>%
  group_by(year, month) %>%
  summarize(mean_temp = mean(temp, na.rm = TRUE),
            .groups = "drop") %>%
  mutate(month_date = ymd(paste(year, month, "01", sep = "-"))) %>%
  arrange(month_date) %>%
  mutate(temp_prior = lag(mean_temp))

head(dlh_month)
lag() shifts a column down by one row — so temp_prior on the February row holds January’s temperature. It only works if the rows are in order and no months are missing, which is why arrange(month_date) comes first.
✏️ Q19: Look at the first row of dlh_month. Why is temp_prior NA there?
▶ Run this:
# Join the temperature onto the ice data ---------------
ice_temp_df <- ice_monthly %>%
  left_join(dlh_month, by = "month_date")

ice_temp_df %>%
  select(month_date, mean_ice, mean_temp, temp_prior)
✏️ Q20: A few rows have NA for mean_temp. Why? (Think about where each record starts and stops.)
▶ Run this:
# Ice cover predicted by THIS month's temperature ------
ice_temp_model <- lm(mean_ice ~ mean_temp, data = ice_temp_df)

summary(ice_temp_model)

ice_temp_df %>%
  ggplot(aes(x = mean_temp, y = mean_ice)) +
  geom_point() +
  geom_smooth(method = "lm")
🔮 Predict first: before you run the next chunk — will last month’s temperature predict ice cover better or worse than this month’s?
▶ Run this:
# Ice cover predicted by LAST month's temperature ------
ice_lag_model <- lm(mean_ice ~ temp_prior, data = ice_temp_df)

summary(ice_lag_model)

ice_temp_df %>%
  ggplot(aes(x = temp_prior, y = mean_ice)) +
  geom_point() +
  geom_smooth(method = "lm")
✏️ Q21: Compare the two R² values. Which predictor won — this month’s temperature, or last month’s?
✏️ Q22: Why would the previous month’s cold predict today’s ice better than today’s cold does? (How long does it take a lake the size of Superior to freeze?)
✏️ Q23: Say the lag model’s slope in plain language: one degree colder last month buys you how much more ice this month?
💡 Key idea: this is the whole arc of the course in one place. Pivot the data so it can be grouped, summarize it to the scale your question lives at, join in a second source keyed on something both tables share, then model it. The lag is the science: a lake is a big thermal flywheel, so its state today reflects the weather of weeks past, not the weather of this morning.
Homework — a different Great Lake
Write it at the bottom of the same script. This part is graded — hand in your answers as # comments.
You built the workflow on Lake Superior. Now run it end to end on a different Great Lake and compare. Pick one:
| File | Lake |
|---|---|
mic.txt |
Michigan |
hur.txt |
Huron |
eri.txt |
Erie |
ont.txt |
Ontario |
Change only the file name in the URL, then repeat Parts 1 → 10. Nothing is filled in — copy your own chunks from above and change what needs changing; for most chunks that is nothing at all.
H1 · Read and pivot your lake
Read it, pivot_longer() it, fix the Nov/Dec dates, and drop the NAs.
✏️ H-Q1: Which lake did you pick?
H2 · Peak ice per winter
slice_max() one row per year.
✏️ H-Q2: The lowest-peak and highest-peak winters in your lake’s record.
H3 · Model the trend
lm(ice_cover ~ year), then plot it with a trend line.
✏️ H-Q3: Slope (% per year), p, R². Significant at α = 0.05?
✏️ H-Q4: Lake Superior’s slope is about −0.7 %/year. Is your lake losing maximum ice faster or slower than Superior, and by how much?
H4 · Month by month
Build the wide summary table with pivot_wider(), flip it back to long, and get every month’s slope the way you did in Part 10.
✏️ H-Q5: Which month is your lake losing ice fastest in? Is it the same month as Superior?
H5 · Explain it
✏️ H-Q6: Using your slope, say in plain language how fast your lake is losing (or gaining) maximum ice cover, and how much total change that adds up to across the whole record.
✏️ H-Q7: Your lake is shallower than Superior. Shallower water holds less heat. Explain in your own words how depth could make one lake’s ice respond faster to the same warming than another’s — and say whether your slope actually came out the way that reasoning predicts.
Review and checkpoint
At this point you should be able to:
Run your whole script top to bottom with Ctrl/Cmd + Shift + Enter. It must run clean.
💡 Key idea: whatever data you pick for your final project, there is a good chance it arrives shaped like
sup.txt— one column per year, site, or category. Recognizing that shape, and knowingpivot_longer()fixes it, will save you real time.
End of Activity 15. Next: two tables that each have half the story, and the joins that put them back together.